
Planet Python
Last update: November 04, 2026 07:48 PM UTC
November 04, 2026
Wing Tips
Getting Started with Autonomous Development in Wing Pro 12.1
This Wing Tip describes how to get started with autonomous development in Wing Pro 12.1. You provide a high-level specification for a new application or a major feature. Wing's Tasks Manager fleshes it out, plans the work, splits it into tasks, and keeps a team of AI agents working on them for hours or days, as needed. The agents write the code, unit tests, and documentation, and commit their work in logical units. You answer questions, review results, and ask for revisions in the Tasks tool, which summarizes work done and decisions made.
Autonomous development shifts your focus from coding details to product design and oversight. You explain your vision. Your team of AI agents takes care of the implementation, end to end, far faster than you could develop the code on your own.
This Wing Tip is part of a series of Wing Tips on working with AI agents in Wing. For more detail on each step, see the How-To Autonomous Development with Wing Pro.
Getting Started
We recommend using a reasonably isolated environment, such as a virtual machine, when using AI agents. At the very least, prevent agents from accessing the keys to your server infrastructure, reading sensitive data, or pushing to your main repository.
(1) Install an AI agent and set up an account for it that covers the amount of work you expect to do. For sustained use, a subscription is generally much cheaper than paying for usage on an API key. Claude Code and Codex are best for autonomous development, since they check the safety of the commands they run. Antigravity, Copilot, and Cursor also work but don't provide the same level of safety. See Setting Up an AI Agent and AI Agent Safety for details.
(2) Install git or Mercurial, if you don't already have one of them. Wing uses it to track, review, and commit each task's changes. You don't need to learn how to use it, since Wing and the agents do that for you.
(3) Create a new project with New Project in the Project menu. Choose New directory and enter a Name, then choose your agent under AI Agent and a Python environment under Python. Leave Create a Git repository checked and click Create Project. Setting up the project for an agent turns on the Tasks Manager and lets it commit autonomously:
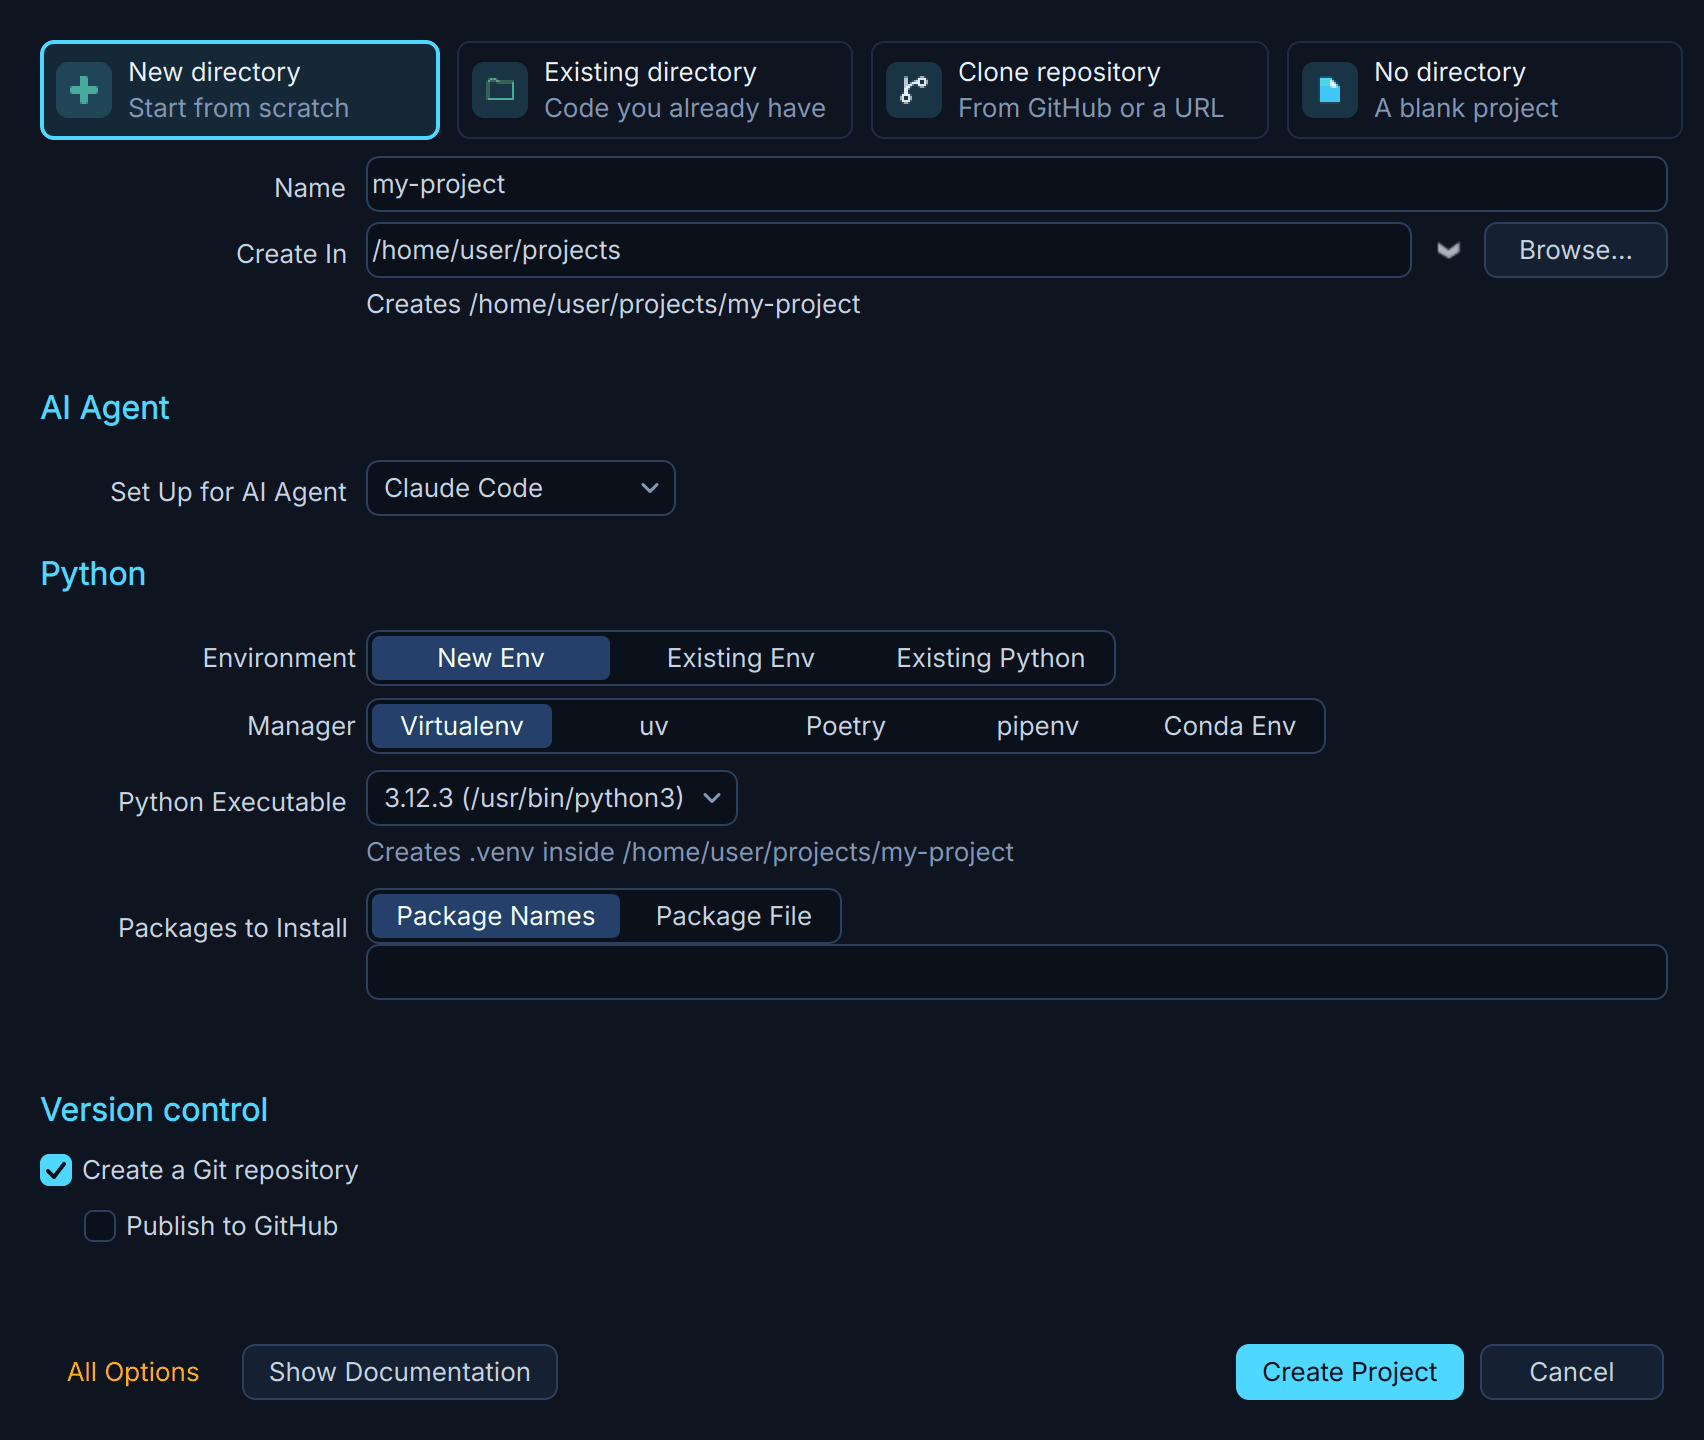
Shown above: Setting up a new project for an AI agent.
(4) Check the Tasks Manager's settings with the settings icon at the right of the Manager's bar, at the top of the Execute tab in the Tasks tool. The defaults are a good place to start. We recommend leaving automatic commits on, so work can go on while you are away. You can still look over every committed task on the Review tab and ask for changes.
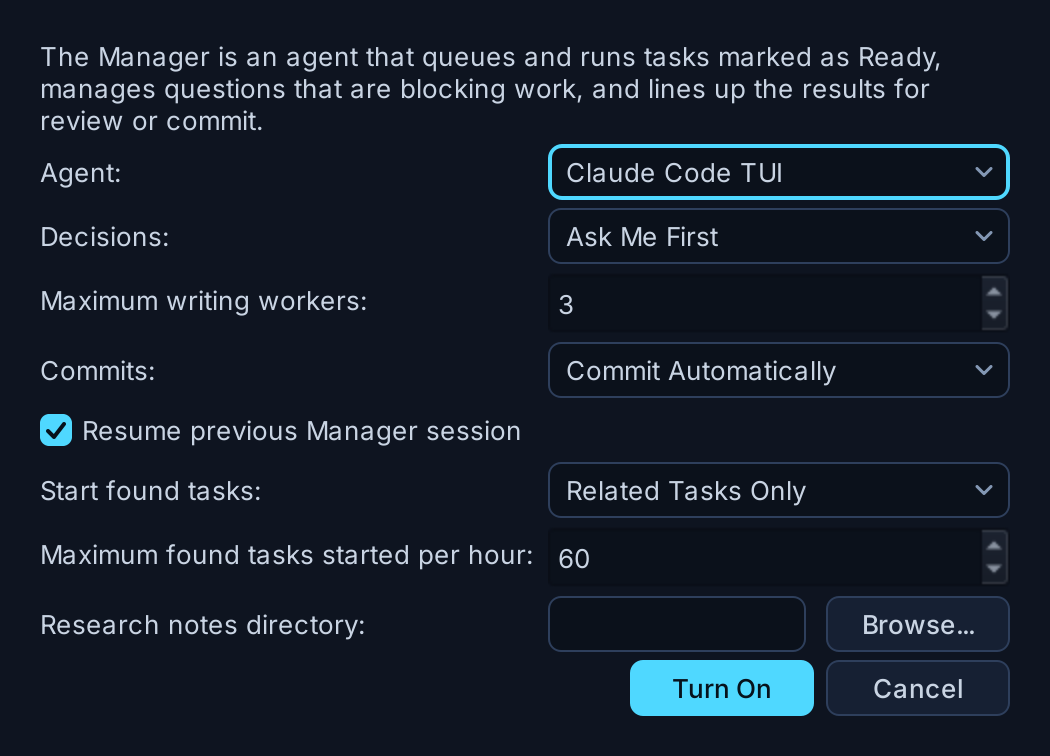
Shown above: The Tasks Manager's settings.
(5) Write a specification or tasks on the Plan tab of the Tasks tool, and mark them Ready by clicking their Draft buttons. A task can be anything from a bug report to a high-level specification for a whole application. Describe what the code should do and any technical constraints that matter from the start. The Manager researches the rest, asks you questions, and writes out the tasks:
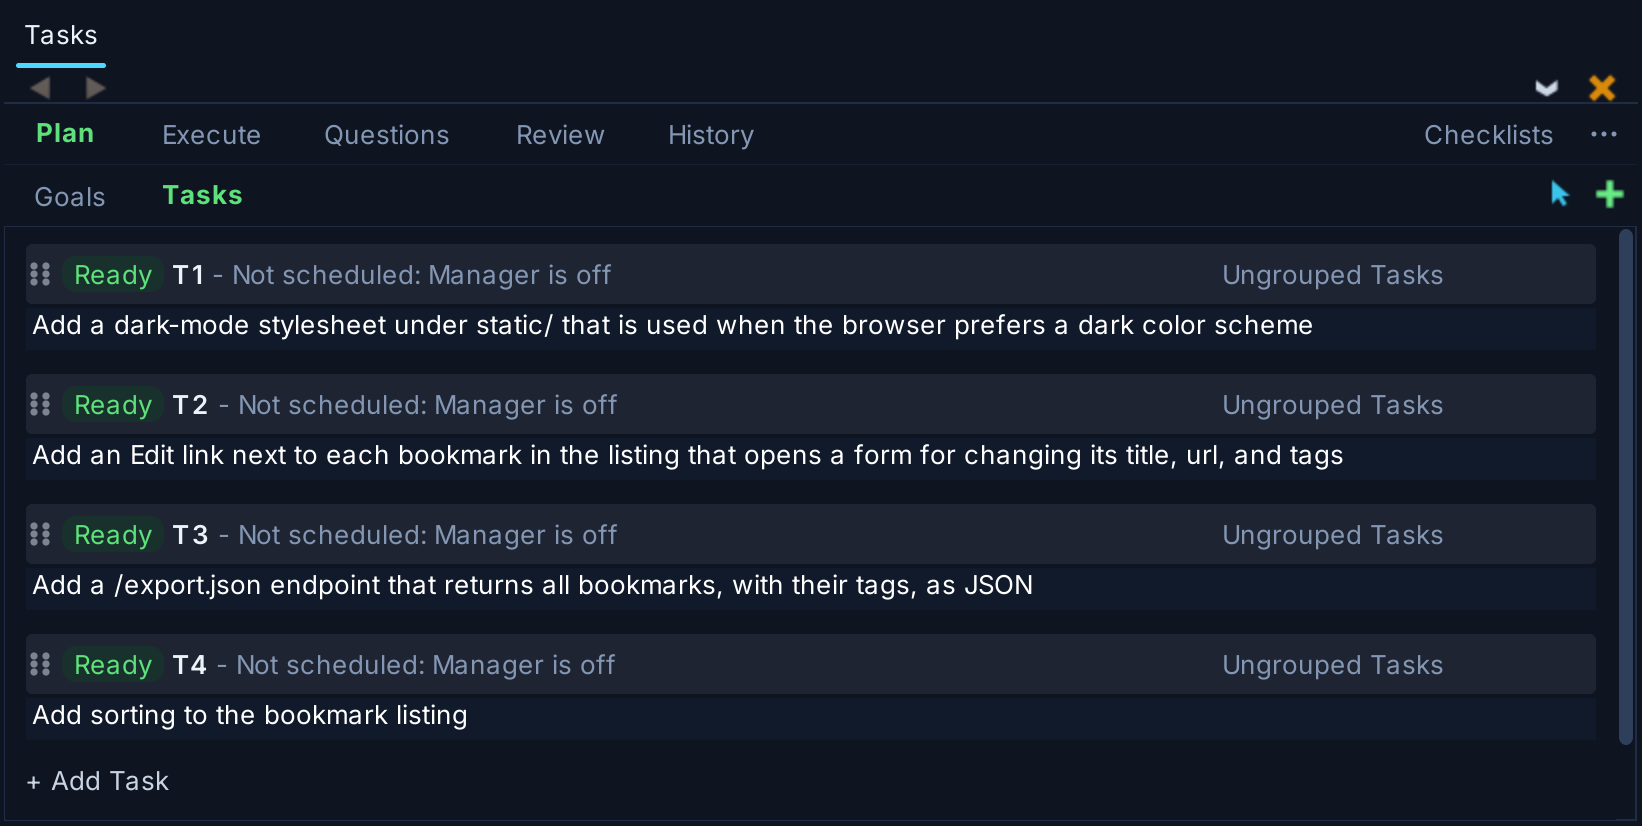
Shown above: A specification on the Plan tab, marked Ready.
You can watch progress on the Execute tab, and click a queue's name to see its session in the AI Agent tool. Problems that agents notice along the way, and follow-up tasks the Manager proposes, appear in the Incoming view on the Plan tab for you to make Ready or dismiss.
(6) Answer questions on the Questions tab when the Manager or a task needs your input. Other tasks keep running while it waits. You can also talk to the Manager directly on the Execute tab, to ask about progress or give it instructions such as "ask me first about anything that changes a file format."
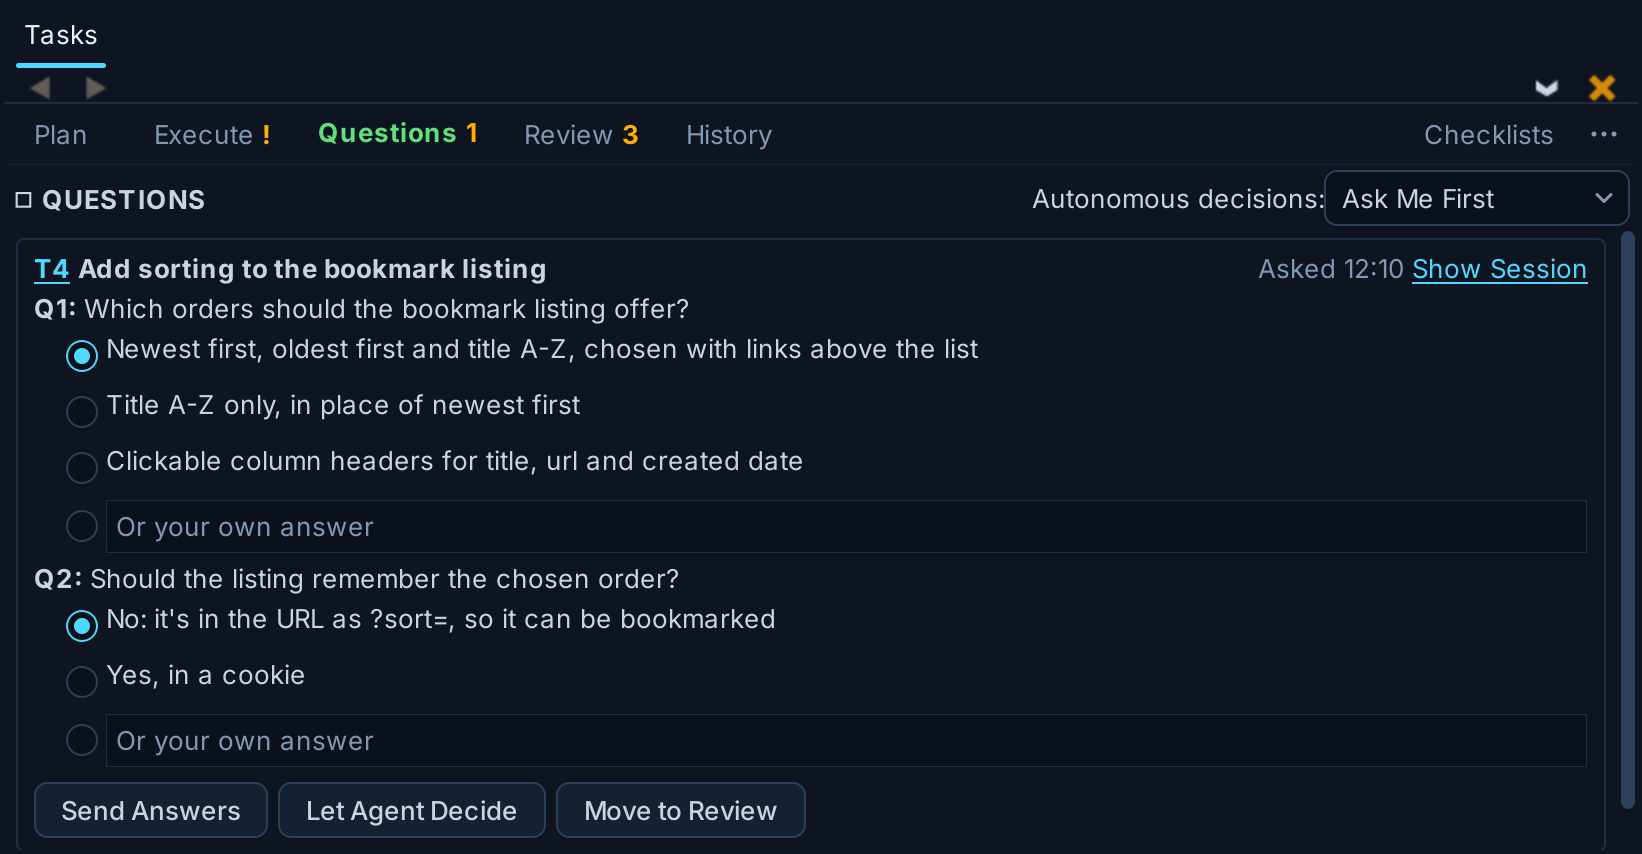
Shown above: Questions about the specification, waiting on the Questions tab.
(7) Review finished work on the Review tab. Each task reports a summary of its changes and the decisions made in it. Use Revise to ask for changes to any decision or the task as a whole. If you are committing work yourself, use Start Review to view and comment on the code, or Commit to commit it without further review.
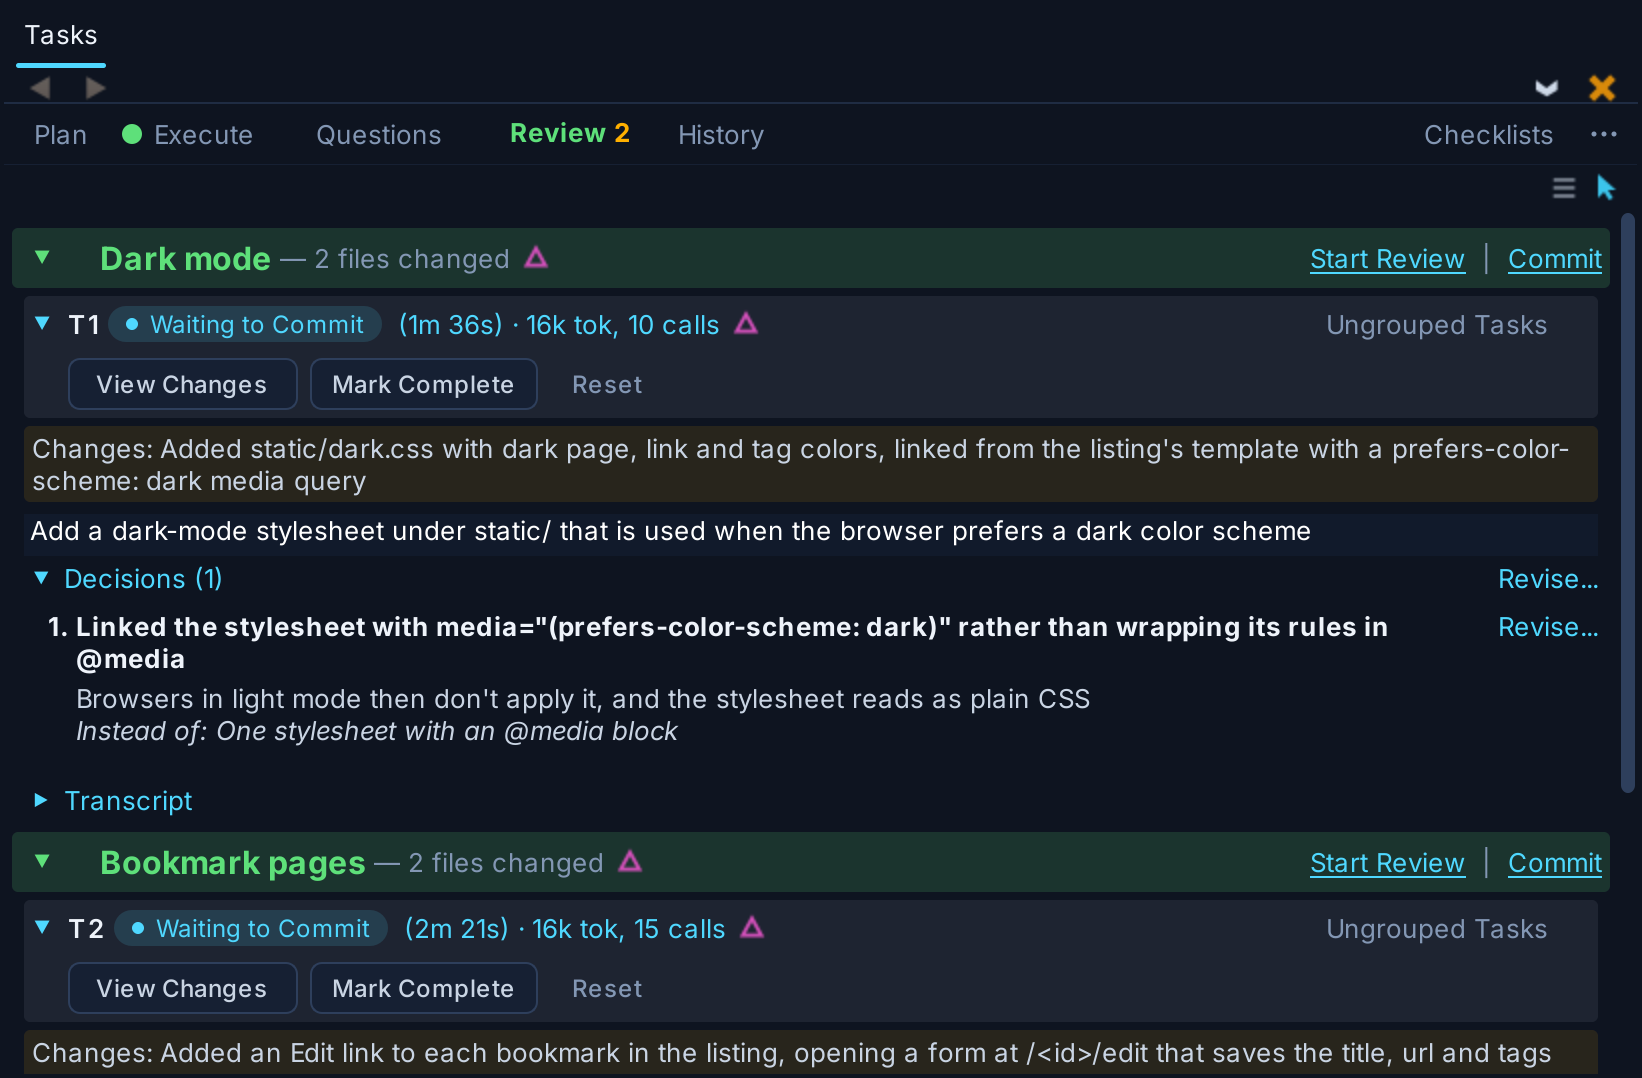
Shown above: A finished task's report on the Review tab, with automatic commits turned off.
Usage Tips
For better results, build tests and cross-checks into your process:
- Ask the Manager early on to set up a way for agents to run your application as a user would, so they can see the results of their work.
- Add tasks at key points that review the code for security flaws, gaps in test coverage, or anything else that matters to you. Problems they find automatically become new tasks.
- Let the Manager commit on a separate branch, and review that branch before merging it into your main branch.
- Use the application yourself, and add tasks for the bugs and improvements you find.
If you're unfamiliar with any of this, just tell the Manager what you need, in the Execute tab of the Tasks tool. It can help you set up your development environment and get started with autonomous software development.
Further Reading
See The Tasks Manager Agent in the Wing Pro manual for details. For examples of complete projects built this way, see the Autonomous Development Demos.
That's it for now! We'll be back soon with more Wing Tips for Wing Pro.
As always, please don't hesitate to email support@wingware.com if you run into problems or have any questions.
November 04, 2026 07:48 PM UTC
Python Morsels
Unnecessary syntax in Python
Unnecessary syntax in Python isn't always unhelpful. An explicit return None, an else, a keyword argument, or a trailing comma can make your code more readable.
Table of contents
Return None
The None in the return statement below isn't necessary:
def item_or_none(sequence, index):
    try:
        return sequence[index]
    except IndexError:
        return None
Using a bare return statement would have worked:
def item_or_none(sequence, index):
    try:
        return sequence[index]
    except IndexError:
        return
In fact, even no return at all would have worked:
def item_or_none(sequence, index):
    try:
        return sequence[index]
    except IndexError:
        pass
Functions return None by default in Python.
But I find return None more explicit and PEP 8 recommends return None in this case:
Be consistent in return statements. Either all return statements in a function should return an expression, or none of them should. If any return statement returns an expression, any return statements where no value is returned should explicitly state this as return None, and an explicit return statement should be present at the end of the function (if reachable).
Explicitly returning None makes it clear that we're returning None deliberately.
The function's return value is significant, unlike most functions that simply return None by default.
An else-return
This else statement is unnecessary:
Read the full article: https://www.pythonmorsels.com/unnecessary-syntax/
November 04, 2026 06:00 PM UTC
The Python Coding Stack
The Second Opinion
November 04, 2026 02:02 PM UTC
death and gravity
pyinfra – simple infrastructure automation in Python
Hi, I'm Adrian, and today I will live demo pyinfra, an infrastructure automation tool.
We will deploy two websites – a landing page and a Python web app – first on a local virtual machine, and then on two remote servers, using only Python code.
Note
This is the edited transcript of a talk I gave at a local DevOps meetup. While part of the "live" aspect is lost in writing, I think it's a pretty decent pyinfra tutorial, so you are welcome to follow along at home.
Contents- About me
- What is pyinfra?
- Why use pyinfra?
- When to use pyinfra?
- The demo
- Operations and facts
- Where are the commands?
- Inventory + nginx setup
- Static site + code reuse
- Web app + secrets
- HTTPS + prod
- Questions?
About me #
Before we talk about pyinfra, I should introduce myself.
I worked at a Fortune 10 company for most of my career, where I did site reliability engineering for the reverse proxy behind some really big websites and two thousand smaller ones, and where I built a data-lake-plus-feature-store for an ML organization.
In my spare time, I write about Python on this website, and I maintain the creatively named reader, a Python feed reader library and web app. Lately I've been working on a hosted version of reader, which is how I ended up using pyinfra.
What is pyinfra? #
pyinfra is a mostly command-line tool that turns Python code into shell commands and runs them on many servers over SSH, in parallel. Think Ansible, but simpler.
for user in ['admin', 'alice', 'bob']:
    server.user(user)

files.put('files/hello.txt', '/etc/motd')

if host.data.get('install_postgres'):
    apt.install('postgresql')
Why use pyinfra? #
I chose pyinfra because, like Ansible, it is declarative – you describe what a server should look like, and pyinfra makes it so – and idempotent – nothing happens if the server is already in the desired state.
Unlike Ansible, there's no YAML – deploys (playbooks) are Python code,
which means you can do anything Python code can do:
you can have fors and ifs,
you can have code completion and type checking,
and you can even import libraries.
Of interest to people using Ansible at larger scales, pyinfra is also faster; in my limited, small-scale experience, it was faster than Ansible with the Mitogen plugin.
In fairness to Ansible, while pyinfra has been around for 10 years, it has fewer built-in operations (modules) and a smaller ecosystem, although that's partially offset by how easy it is to write custom operations.
When to use pyinfra? #
pyinfra use cases follow from what it does – configuring servers over SSH.
As such, pyinfra is good for boring, cloud-agnostic architectures, from lots of servers with different roles all the way down one-computer programming, where it still makes deploys reproducible and prevents drift.1
It is pretty easy to learn too, so it's a good fit for self-hosting and home servers, and even if you don't use it for configuration management, pyinfra gives you a convenient way of running ad-hoc commands on fleets of servers.2
Simplicity comes with limitations: fully-automated pipelines are extra work, there's no built-in pull mode, and care is needed if multiple people run deploys at the same time. Nevertheless, you can get quite far with well-structured deploys, and there's a Python API for building stuff on top if you really need to.
The demo #
I'll try to focus on the interesting parts, but you can find the entire code on GitHub.
At the end of the demo, we'll have two websites, a landing page and a Python web app, deployed in two stages – a local virtual machine for beta:
.--- pyinfra.local ---.- app.pyinfra.local -.
|                   nginx                   |
|   static website    :   Python web app    |
'-------------------------------------------'
...and two separate servers for prod:
.--- pyinfra.a.c ----. .- app.pyinfra.a.c --.
|       nginx        | |       nginx        |
|   static website   | |   Python web app   |
'--------------------' '--------------------'
apt.update(name="apt update", cache_time=24 * 3600)

apt.packages(['nginx', 'python3-certbot-nginx'], name="install nginx")

disable_default = files.link(
    name="disable default site",
    path='/etc/nginx/sites-enabled/default',
    present=False,
)
server.service(
    name="reload nginx",
    service='nginx',
    reloaded=True,
    _if=disable_default.did_change,
)

if host.data.get('home_domain'):
    local.include('tasks/home.py')
if host.data.get('app_domain'):
    local.include('tasks/app.py')
Operations and facts #
First, we should get familiar with two basic pyinfra concepts.
Operations change the server in some way; most are declarative and idempotent, and you use them to ensure state. A Python file containing operations is called a deploy.
Here's a simple deploy with one operation
that says "I want hello.txt to exist":
from pyinfra.operations import files

files.file('hello.txt', present=True)
If we run this deploy (below, on my @local machine), we see a list of all the operations and on which hosts they will produce changes, and are asked to approve them:
$ pyinfra @local examples/create_file.py
--> Loading config...
--> Loading inventory...
--> Connecting to hosts...
    [@local] Connected

--> Preparing operation files...
    Loading: examples/create_file.py
    [@local] Ready: examples/create_file.py

--> Detected changes:
    Operation                              Change       Conditional Change
    files.file (hello.txt, present=True)   1 (@local)   -

    ...
    Press enter to execute...
If we do, we see the operations running and their outcomes:
    Press enter to execute... [Enter]
--> Beginning operation run...
--> Starting operation: files.file (hello.txt, present=True)
    [@local] Success

--> Results:
    Operation                              Hosts   Success   Error   No Change
    files.file (hello.txt, present=True)   1       1         -       -
    Grand total                            1       1         -       -

--> Disconnecting from hosts...
And now hello.txt exists:
$ ls hello.txt
hello.txt
Since files.file is idempotent, nothing happens if we run the deploy again:
$ pyinfra @local examples/create_file.py
...
--> Detected changes:
    Operation                              Change   Conditional Change
    files.file (hello.txt, present=True)   -        -
...
--> Beginning operation run...
--> Starting operation: files.file (hello.txt, present=True)
    [@local] No changes
...
Facts gather data about the target host; you use them to control operations.
Here's a deploy that installs the Apache web server:
from pyinfra import host
from pyinfra.facts.server import LinuxName
from pyinfra.operations import server

if host.get_fact(LinuxName) in ['Ubuntu', 'Debian']:
    server.packages('apache2')
else:
    server.packages('httpd')
The package is usually called httpd,
but Debian-based distributions call it apache2, so
we use the LinuxName fact to detect where we are
and pass the right name to the server.packages operation.
My machine is a Mac,
so the httpd branch is chosen:3
$ pyinfra @local examples/install_apache.py --dry
...
--> Detected changes:
    Operation                 Change       Conditional Change
    server.packages (httpd)   1 (@local)   -
...
Where are the commands? #
Before we look at debug output, let's see how pyinfra operations are implemented.
Here's a simplified version of the files.file implementation:
@operation()
def file(path: str, present: bool = True):
    info = host.get_fact(File, path=path)

    if info is None and present:
        yield f"touch {quote(path)}"

    elif info and not present:
        yield f"rm -f {quote(path)}"
The structure is similar for all operations: read the host state using facts, diff it against the desired state, and return commands to reach the desired state if they don't match.
Here's another deploy
that says "I want hello.txt to not exist":
from pyinfra.operations import files

files.file('hello.txt', present=False)
With --debug,
we can see the commands being run
during each execution phase.
During the prepare phase (before approval), pyinfra runs the deploy code once per host to load operations, and then runs each operation to see if it returns commands, without running the commands themselves (this is how "detected changes" works).
Running operations runs facts, which results in read-only commands being run:
$ pyinfra @local examples/delete_file.py --debug
...
--> Preparing operation files...
    Loading: examples/delete_file.py
    [pyinfra.api.operation] Adding operation, {'files.file'}, ...
    [pyinfra.api.facts] Getting fact: files.File (path=hello.txt)
[pyinfra.connectors.local] --> Running command on localhost: sh -c '! (test -e hello.txt || test -L hello.txt ) || ( stat -c '"'"'user=%U group=%G mode=%A atime=%X mtime=%Y ctime=%Z size=%s %N'"'"' hello.txt 2> /dev/null || stat -f '"'"'user=%Su group=%Sg mode=%Sp atime=%a mtime=%m ctime=%c size=%z %N%SY'"'"' hello.txt || ls -ld hello.txt )'
    [pyinfra.api.facts] [@local] Loaded fact files.File (path=hello.txt)
    [@local] Ready: examples/delete_file.py

--> Detected changes:
    Operation                               Change       Conditional Change
    files.file (hello.txt, present=False)   1 (@local)   -

    ...
    Press enter to execute...
During the execute phase, pyinfra runs the previously loaded operations again, but this time it runs the commands returned by them too:
    Press enter to execute... [Enter]
--> Beginning operation run...
--> Starting operation: files.file (hello.txt, present=False)
    [pyinfra.api.facts] Getting fact: files.File (path=hello.txt)
[pyinfra.connectors.local] --> Running command on localhost: sh -c '! (test -e hello.txt || test -L hello.txt ) || ( stat -c '"'"'user=%U group=%G mode=%A atime=%X mtime=%Y ctime=%Z size=%s %N'"'"' hello.txt 2> /dev/null || stat -f '"'"'user=%Su group=%Sg mode=%Sp atime=%a mtime=%m ctime=%c size=%z %N%SY'"'"' hello.txt || ls -ld hello.txt )'
    [pyinfra.api.facts] [@local] Loaded fact files.File (path=hello.txt)
[pyinfra.connectors.local] --> Running command on localhost: sh -c 'rm -f hello.txt'
    [@local] Success
...
Inventory + nginx setup #
So far we've been using my local machine as target host, but we want beta to be as similar to prod as possible, so I've set up an Ubuntu virtual machine with Vagrant.
Also, you will typically use an inventory file containing groups of hosts instead of passing individual hosts directly to the CLI. For our demo, we need just one group:
# group_name = [host1, host2, ...]

my_hosts = ['pyinfra.local']

# you can have more groups:
#
# db_servers = ['db-1.net', 'db-2.net']
# web_servers = [i.hostname for i in aws.ec2.list_instances(asg='my-asg')]
Since the inventory is a Python file, groups don't have to be list literals – you could, for example, import a library and list instances in an autoscaling group dynamically.
Here's how you use an inventory to run arbitrary commands:
$ pyinfra inventories/beta.py exec -- lsb_release -d
...
--> Beginning operation run...
--> Starting operation: server.shell (lsb_release -d)
[pyinfra.local] Description: Ubuntu 26.04.1 LTS
    [pyinfra.local] Success
...
We'll use nginx for both of our websites, which means we need to install it first.
Here's what the main deploy looks like (minus imports):
| infra/deploy.py | |
|---|---|
| |
We update the package cache,
we install nginx,
we disable the default "Welcome to nginx!" site,
and then we reload the nginx config.
To avoid unnecessary reloads,
we use the _if global argument
to reload only if the previous operation actually ran.
In theory, we could use a fact to gate the last two operations instead:
apt.packages(...)
if host.get_fact(Link, '/etc/nginx/sites-enabled/default'):
    files.link(...)
    server.service(...)
...but that if happens in the prepare phase,
when nginx (and the symlink) hasn't been installed yet,
so they would be skipped on the first run.
If we run the deploy, no change is detected for "disable default site" (no symlink yet):
$ pyinfra inventories/beta.py deploy.py
...
--> Detected changes:
    Operation              Change              Conditional Change
    apt update             1 (pyinfra.local)   -
    install nginx          1 (pyinfra.local)   -
    disable default site   -                   -
    reload nginx           -                   1 (pyinfra.local)

    Detected changes may not include every change pyinfra will execute.
    Hidden side effects of operations may alter behaviour of future operations,
    this will be shown in the results. The remote state will always be updated
    to reflect the state defined by the input operations.

    Press enter to execute... [Enter]
...
--> Results:
    Operation              Hosts   Success   Error   No Change
    apt update             1       1         -       -
    install nginx          1       1         -       -
    disable default site   1       1         -       -
    reload nginx           1       1         -       -
...
...but the operation does run, as the prophecy foretold ("side effects of operations may alter behaviour of future operations").
Static site + code reuse #
With nginx installed, we can proceed to the static home page.
We'll put the operations in a separate file that we include in the main deploy, which in addition to keeping code tidy, allows specific tasks to be conditional:
| infra/deploy.py | |
|---|---|
| |
Host data is arbitrary data associated with hosts in the inventory file:
# group_name = [(host1, {'some custom': 'host data'}), ...]

my_hosts = [
    ('pyinfra.local', {
        'home_domain': 'pyinfra.local',
    }),
]  # fmt: skip
The home page deploy itself is pretty straightforward:
| infra/tasks/home.py | |
|---|---|
| |
There's one operation that synchronizes files from a local directory to a remote one, and another operation that sets up an nginx site using the domain from host data.
Except nginx.site isn't actually an operation,
but a packaged deploy;
besides the function definition that makes it reusable,
it looks like any other deploy:
| infra/modules/nginx.py | |
|---|---|
| |
files.template uses Jinja, so we can have a base template for all HTTP sites:
server {
    listen 80;
    listen [::]:80;
    server_name {{ domain }};

    {% block server %}{% endblock %}
}
...that we then extend with site-specific configuration:
{% extends 'templates/nginx/http.conf' %}

{% block server -%}

    location / {
        root /opt/home;
    }

{%- endblock %}
Passing --diff shows the rendered template, which is pretty neat:
$ pyinfra inventories/beta.py deploy.py --diff
...
--> Preparing operation files...
    Loading: deploy.py
    [pyinfra.local] Will create /etc/nginx/sites-available/pyinfra.local
      @@ -0,0 +1,9 @@
      + server {
      +     listen 80;
      +     listen [::]:80;
      +     server_name pyinfra.local;
      +
      +     location / {
      +         root /opt/home;
      +     }
      + }

    [pyinfra.local] Ready: deploy.py

--> Detected changes:
    Operation                             Change              Conditional Change
    apt update                            -                   -
    install nginx                         -                   -
    disable default site                  -                   -
    reload nginx                          -                   1 (pyinfra.local)
    tasks/home.py | sync files            1 (pyinfra.local)   -
    tasks/home.py | nginx site | write    1 (pyinfra.local)   -
    tasks/home.py | nginx site | enable   1 (pyinfra.local)   -
    tasks/home.py | nginx site | reload   -                   1 (pyinfra.local)
...
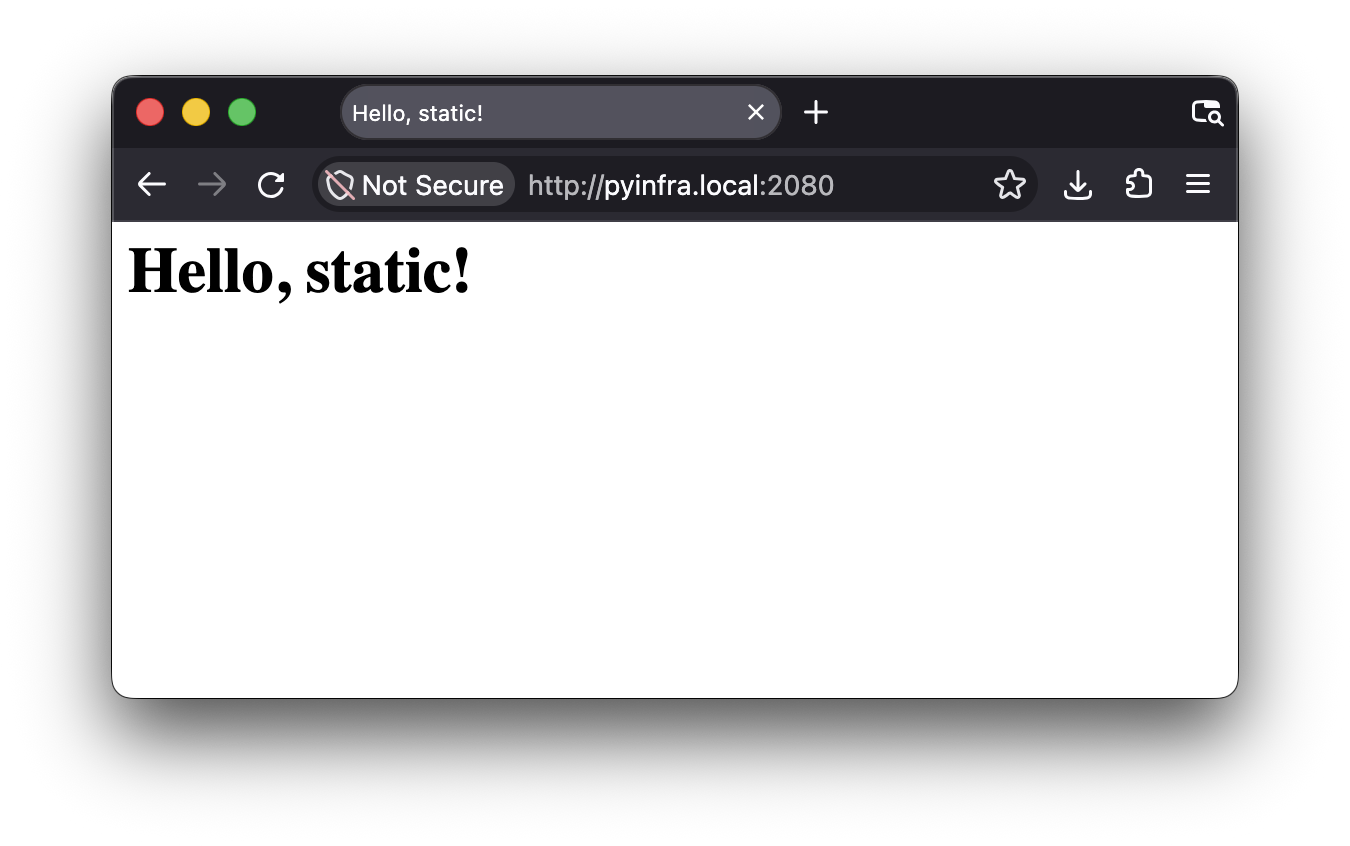
And now we have a static site!
Web app + secrets #
The web application is a simple Flask app that we can install with pip:
$ tree app
app
├── app
│   ├── __init__.py
│   ├── static
│   │   └── style.css
│   └── templates
│       └── index.html
└── pyproject.toml
We serve it using a traditional Gunicorn being nginx on a Unix socket setup:
   :80, :443
       |
.-------------.
|    nginx    |  groups: app-socket, www-data
'-------------'
       |
    app.sock     groups: app-socket
       |
.- Gunicorn --.
|   web app   |  groups: app-socket, app
'-------------'
The deploy for it is slightly bigger, but hopefully still straightforward.
We have operations to create users and groups:
| infra/tasks/app.py | |
|---|---|
| |
...to create a virtual environment with our app and its dependencies:
| infra/tasks/app.py | |
|---|---|
| |
...to create and start a systemd service for Gunicorn:
| infra/tasks/app.py | |
|---|---|
| |
...and finally to configure nginx:
| infra/tasks/app.py | |
|---|---|
| |
In addition, Flask needs a secret key, which usually comes from a config file:
| infra/tasks/app.py | |
|---|---|
| |
The question is, where do we store the secret key before writing the config?
The simple (and wrong) solution is to hardcode it in the deploy or in the template; unencrypted-secrets-in-version-control issue aside, we'd also like the secrets to be different between beta and prod.
As I said, a deploy is a Python file, so we can do anything: we can get them from a password manager, a security key, or even an encrypted file. To illustrate the point, here's a simple function that reads named secrets from an unencrypted JSON file:4
import json
from pyinfra import host

secrets_path = 'secrets.json'

def get_secret(name, *, stage=None):
    if not stage:
        stage = host.data.stage

    with open(secrets_path) as f:
        data = json.load(f)

    if secret := data.get(stage, {}).get(name):
        return secret

    raise RuntimeError(f"secret {name!r} for stage {stage!r} not found")
The stage comes from host data,
this time not in the inventory,
but in a group data file
that applies to all hosts in a group
(beta, the inventory name, is an implicit group):
stage = 'beta'
The config template looks like this:
SECRET_KEY = {{ '{!r}'.format(get_secret('app_secret_key')) }}
Deploying looks the same, only with way more operations:
$ pyinfra inventories/beta.py deploy.py
...
--> Results:
    Operation                             Hosts   Success   Error   No Change
    ...
    Grand total                           23      15        -       8
...
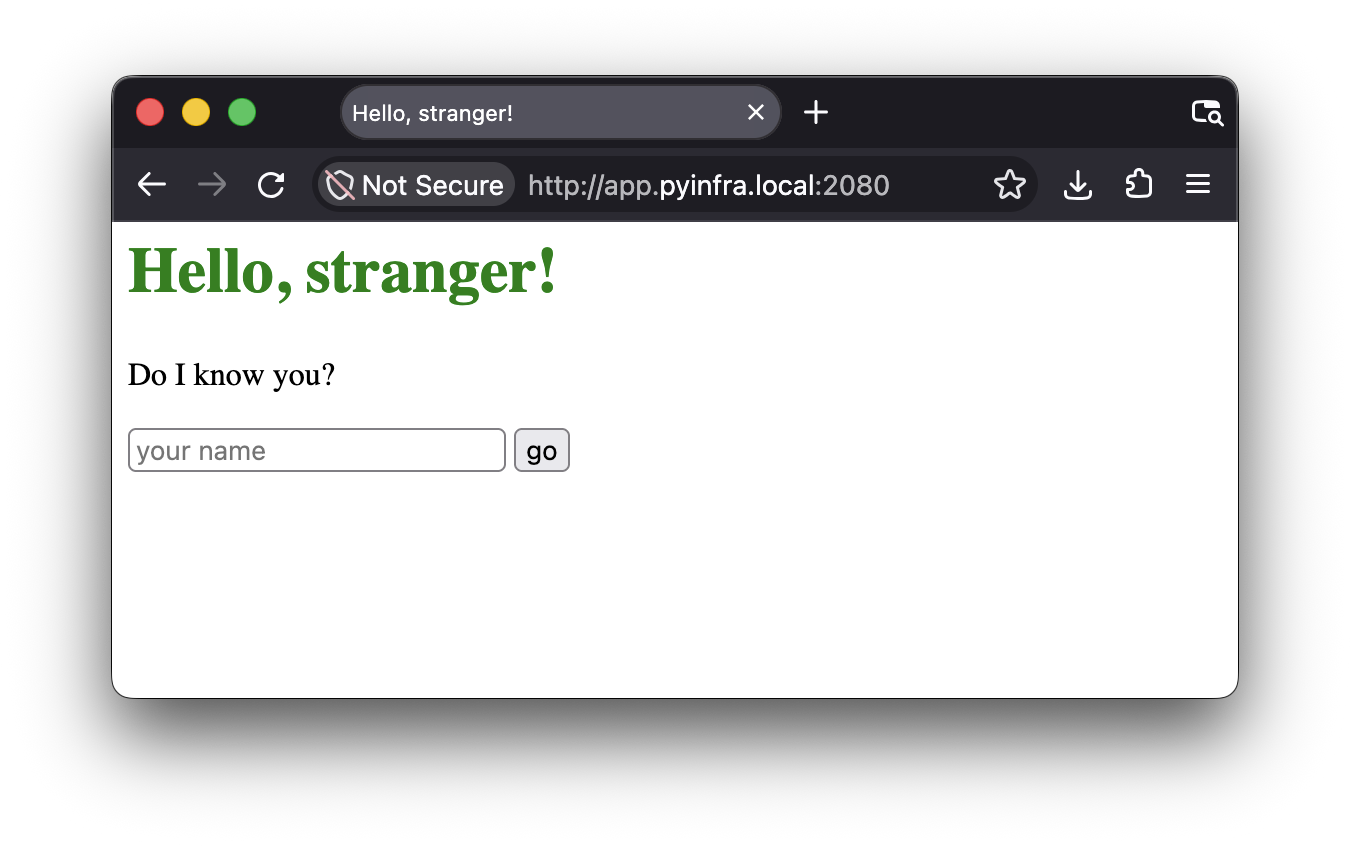
And now we have a web app:
HTTPS + prod #
That's a nice looking web app, but it would be even nicer if it were not "not secure". This requires HTTPS, which requires a TLS certificate.
Fortunately, those are easy to get these days – Let's Encrypt provides free certificates, and Certbot will request, install, and renew them automatically.
Unfortunately, there's no built-in Certbot operation, so we have to write a custom one:
| infra/modules/certbot.py | |
|---|---|
| |
Like in the initial example, we read the host state using a fact and then return commands if it doesn't match the desired state. The fact is custom too:
| infra/modules/certbot.py | |
|---|---|
| |
And we already have a convenient place where we can use the operation:
| infra/modules/nginx.py | |
|---|---|
| |
Also unfortunately, Certbot needs a resolvable domain name to work, so we can't test this using the beta virtual machine... but we can always test in prod. ( ≖‿ ≖ )
Here's a new inventory with two hosts, each with its own domain and HTTPS enabled:
my_hosts = [
    ('pyinfra.andgravity.com', {
        'home_domain': 'pyinfra.andgravity.com',
    }),
    ('app.pyinfra.andgravity.com', {
        'app_domain': 'app.pyinfra.andgravity.com',
    }),
]  # fmt: skip
stage = 'prod'
nginx_https = True
I say we just go for it:
$ pyinfra inventories/prod.py deploy.py --yes
... stuff happens ...
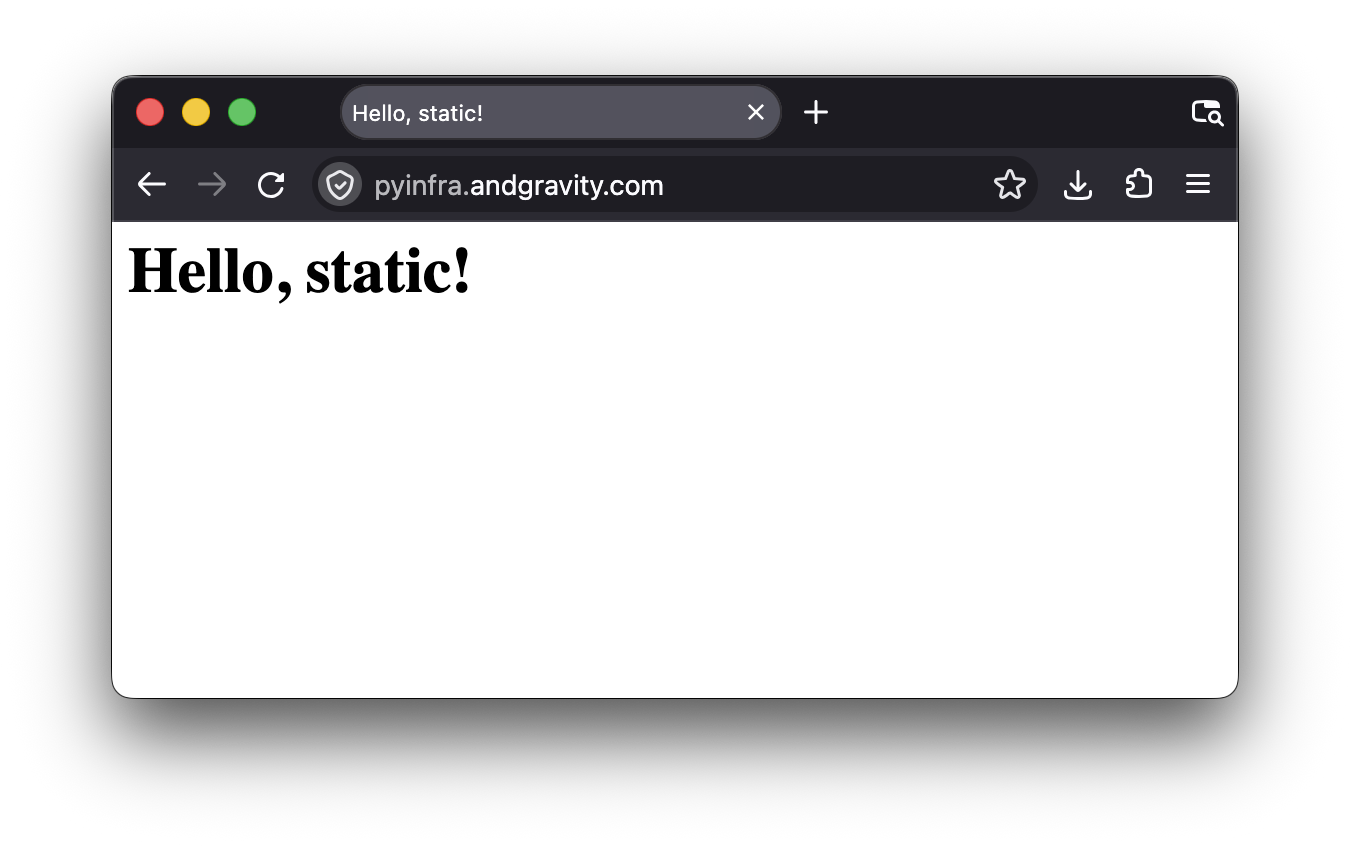
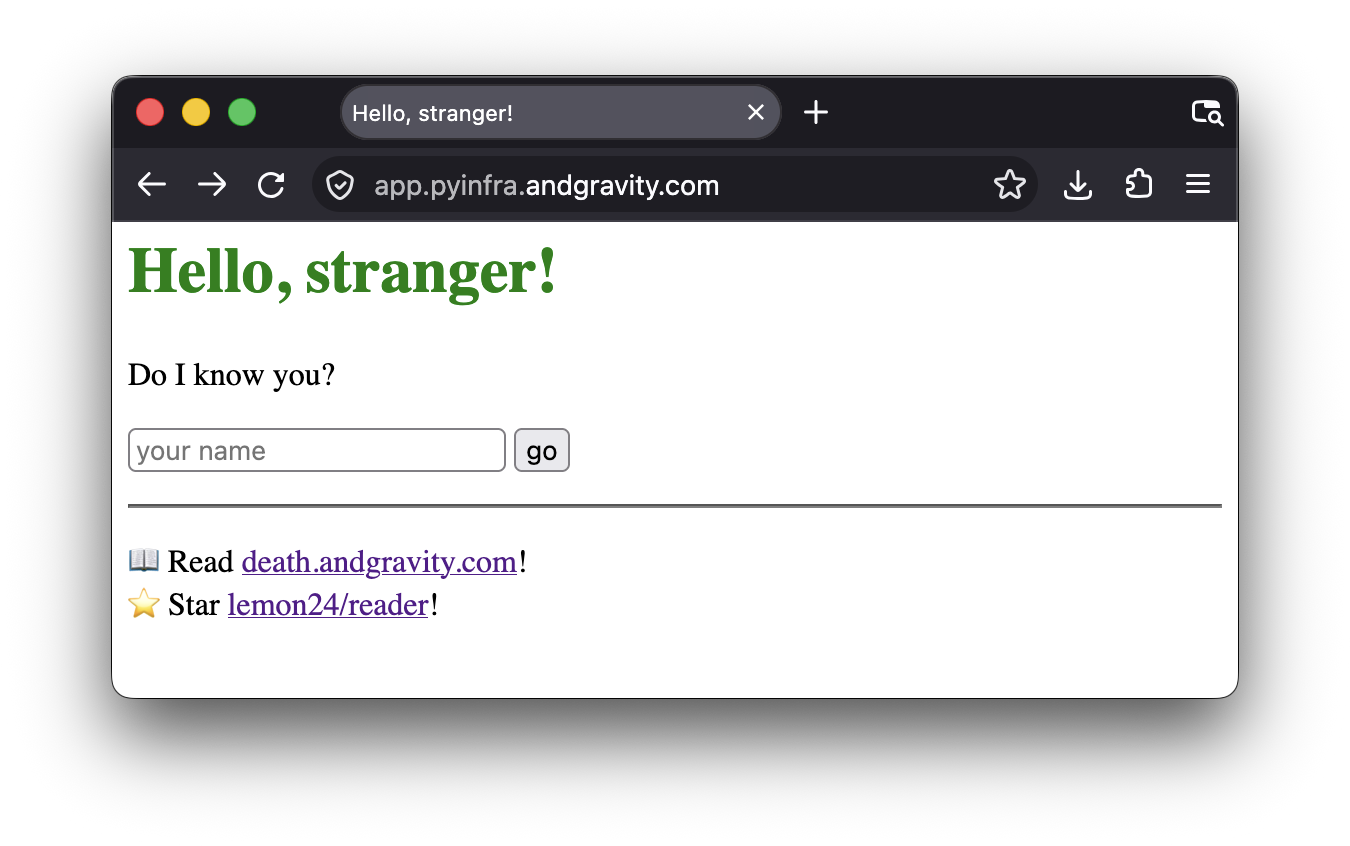
One minute later, there are ✨ two new websites ✨ on the internet:5
Questions? #
Can I use pyinfra from an interactive Python shell? #
Yes, although it doesn't look exactly like a deploy and there's a bit of boilerplate, which you can reduce by using (undocumented) CLI code to e.g. load inventories.
Can I use pyinfra to provision cloud resources? #
No, you'd use something like Terraform for that.
Based on this 2020 comment from the author and on pyinfra's evolution since, it's unlikely it will ever grow beyond "commands over SSH", which is a feature IMHO.
If I may editorialize further, maybe if you had fewer resources you wouldn't need an automated way to provision them; here's some propaganda for you:
- One machine can go pretty far if you build things properly
- One process programming notes (with Go and SQLite)
- Hidden Secrets to Making a New Microservices Cluster a Success
Can you use pyinfra with cloud inventories? #
Yes, kinda.
As mentioned when introducing inventories, you can use your cloud's Python SDK to list hosts directly in the inventory file (shouldn't take more than twenty lines of code).
If you use Terraform, there's also a @terraform connector6
that allows using an output variable as inventory
(pyinfra @terraform/name ...).
Anyway, that's it for now.
Learned something new today? Share it with others, it really helps!
Want to know when new articles come out? Subscribe via email to get new stuff straight to your inbox!
And you're bound to have extra dev and pre-prod machines anyway. [return]
Say you have a memory leak during a high traffic period and need to reload stuff once in a while until you can find the root cause. [return]
Deploy deploy code runs once per host, so you could have different branches on different hosts within the same run. [return]
Which you absolutely should not do, use keyrings.cryptfile instead. [return]
Well, not anymore, there's no point in paying to host this :) [return]
I didn't talk about them in the article, but connectors execute commands and/or generate inventories; we've used the default @ssh connector and @local. [return]
November 04, 2026 01:45 PM UTC
Python Software Foundation
Joshua Mcshannon Joins the PSF as Infrastructure Engineer
The Python Software Foundation (PSF) is excited to announce our newest staff member and Infrastructure Engineer, Joshua Mcshannon, reporting to Director of Engineering Jacob Coffee. Joshua brings over 16 years of technical expertise from various backgrounds including bootstrapped startups and big tech. Most recently he built an AI-integrated learning platform for cybersecurity students and taught secure web application development along with DevOps/platform engineering.

Joshua will focus on reducing operational complexity and toil of the PSF infrastructure, optimizing to better serve the community at large and internal PSF platforms that CPython core developers and staff members rely on daily; this includes services like python.org, PyPI, and infrastructure behind PyCon US. With Joshua on the team, the PSF will gain much needed redundancy for on-call rotations as well as capacity for new infrastructure projects.
“We put people on the moon with a Ti-82, I’m sure we can figure something out.”
Joshua has already shown great initiative in the work that the PSF has, diving deep into our Kubernetes infrastructure and preparing improvements to keep costs low. Away from the keyboard you’ll find him at a local show, on a nature trail, or at a flea market with his family. Say hello when you see Joshua in the repos, issue trackers, mailing lists, and on discuss.python.org!
About the Python Software Foundation
The Python Software Foundation (PSF) is a non-profit whose mission is to promote, protect, and advance the Python programming language, and to support and facilitate the growth of a diverse and international community of Python programmers. The PSF supports the Python community using corporate sponsorships, grants, and donations. Are you interested in sponsoring or donating to the PSF so it can continue supporting Python and its community? Check out our sponsorship program, donate directly here, or contact our team!
November 04, 2026 08:59 AM UTC
Python GUIs
Change color in QProgressBar delegate — How to dynamically change QProgressBar colors in a QTableView delegate
How can I change the color of a QProgressBar delegate in a QTableView when a process starts or stops? I'm using a delegate to show an indeterminate progress bar (with
setRange(0, 0)), and I want it to be green when running and red when stopped, but replacing the delegate doesn't seem to redraw the color.
The issue here comes from how delegates and persistent editors interact. When you call openPersistentEditor, Qt creates the editor widget and keeps it alive. Replacing the delegate on a row doesn't automatically close and recreate those existing editors — so even though you're assigning a new ProgressBarDelegate with a different color, the old progress bar widget is still sitting there unchanged.
The solution is to store the color information in the model data and have a single delegate read that color when it creates or updates the editor. This way, when the data changes, the delegate can update the editor's stylesheet accordingly.
Let's walk through how to set this up properly.
Store state in the model, not the delegate
Rather than creating a new delegate every time a button is clicked, store the running/stopped state in the model itself. You can use a custom Qt.ItemDataRole (or just Qt.UserRole) to hold the color or state for each row. The delegate then reads this value when painting or configuring the editor.
This keeps your architecture clean: the model holds the data, and the delegate is responsible only for presentation.
Use setEditorData to update the progress bar
The setEditorData method on your delegate is called whenever the model data changes for an index that has a persistent editor. This is where you update the progress bar's stylesheet based on the current state.
Here's how to write a ProgressBarDelegate that reads a color from the model:
class ProgressBarDelegate(QtWidgets.QStyledItemDelegate):
    def paint(self, painter, option, index):
        if index.column() == 2:
            if (
                isinstance(self.parent(), QtWidgets.QAbstractItemView)
                and self.parent().model() is index.model()
            ):
                self.parent().openPersistentEditor(index)
        QtWidgets.QStyledItemDelegate.paint(self, painter, option, index)

    def createEditor(self, parent, option, index):
        editor = QtWidgets.QProgressBar(parent)
        editor.setRange(0, 0)
        editor.setTextVisible(False)
        return editor

    def setEditorData(self, editor, index):
        color = index.data(QtCore.Qt.ItemDataRole.UserRole)
        if color:
            editor.setStyleSheet(
                f"QProgressBar::chunk {{background-color: {color}; "
                f"width: 20px; margin: 0.5px;}}"
            )

    def updateEditorGeometry(self, editor, option, index):
        editor.setGeometry(option.rect)
The delegate no longer stores any color itself. Instead, setEditorData looks up the color from Qt.UserRole on the model index and applies it to the stylesheet. Every time you call setData on the model with Qt.UserRole, Qt will automatically call setEditorData on the persistent editor for that index.
Update the model when the button is clicked
In your button click handler, instead of creating a new delegate, just update the model data:
def on_button_clicked(self, index):
    model = self.table_view.model()
    progress_index = model.index(index.row(), 2)

    current_state = progress_index.data(QtCore.Qt.ItemDataRole.DisplayRole)

    if current_state is None or current_state == 0:
        model.setData(progress_index, "green", QtCore.Qt.ItemDataRole.UserRole)
        model.setData(progress_index, 1, QtCore.Qt.ItemDataRole.DisplayRole)
    else:
        model.setData(progress_index, "red", QtCore.Qt.ItemDataRole.UserRole)
        model.setData(progress_index, 0, QtCore.Qt.ItemDataRole.DisplayRole)
The DisplayRole tracks the state (1 for running, 0 for stopped), and UserRole holds the color string. When setData is called, the model emits dataChanged, which triggers setEditorData on the persistent editor — and the progress bar updates its color.
Complete working example
Here's the full example putting everything together. The QTableView shows a list of paths, each with a Start/Stop button and an indeterminate progress bar. Clicking the button toggles the progress bar between green and red using a single delegate that reads color from the model.
import sys

from PySide6 import QtCore, QtGui, QtWidgets


class ProgressBarDelegate(QtWidgets.QStyledItemDelegate):
    def paint(self, painter, option, index):
        if index.column() == 2:
            if (
                isinstance(self.parent(), QtWidgets.QAbstractItemView)
                and self.parent().model() is index.model()
            ):
                self.parent().openPersistentEditor(index)
        QtWidgets.QStyledItemDelegate.paint(self, painter, option, index)

    def createEditor(self, parent, option, index):
        editor = QtWidgets.QProgressBar(parent)
        editor.setRange(0, 0)
        editor.setTextVisible(False)
        return editor

    def setEditorData(self, editor, index):
        color = index.data(QtCore.Qt.ItemDataRole.UserRole)
        if color:
            editor.setStyleSheet(
                f"QProgressBar::chunk {{background-color: {color}; "
                f"width: 20px; margin: 0.5px;}}"
            )

    def updateEditorGeometry(self, editor, option, index):
        editor.setGeometry(option.rect)


class PushButtonDelegate(QtWidgets.QStyledItemDelegate):
    clicked = QtCore.Signal(QtCore.QModelIndex)

    def paint(self, painter, option, index):
        if (
            isinstance(self.parent(), QtWidgets.QAbstractItemView)
            and self.parent().model() is index.model()
        ):
            self.parent().openPersistentEditor(index)
        QtWidgets.QStyledItemDelegate.paint(self, painter, option, index)

    def createEditor(self, parent, option, index):
        button = QtWidgets.QPushButton(parent)
        button.clicked.connect(lambda *args, ix=index: self.clicked.emit(ix))
        return button

    def setEditorData(self, editor, index):
        editor.setText("Start/Stop")

    def updateEditorGeometry(self, editor, option, index):
        editor.setGeometry(option.rect)


class MainWindow(QtWidgets.QMainWindow):
    def __init__(self, parent=None):
        super().__init__(parent)
        self.setFixedSize(600, 300)

        self.table_view = QtWidgets.QTableView()
        layout = QtWidgets.QHBoxLayout()
        layout.addWidget(self.table_view)
        cw = QtWidgets.QWidget()
        cw.setLayout(layout)
        self.setCentralWidget(cw)

        self.init_model()

        self.button_delegate.clicked.connect(self.on_button_clicked)

    def init_model(self):
        headers = ["Path", "Control", "Progress"]

        self.button_delegate = PushButtonDelegate(self.table_view)
        self.progress_delegate = ProgressBarDelegate(self.table_view)

        self.model = QtGui.QStandardItemModel()
        self.model.setHorizontalHeaderLabels(headers)

        for row in range(5):
            self.model.setItem(
                row, 0, QtGui.QStandardItem(f"some_path{row}")
            )
            self.model.setItem(row, 1, QtGui.QStandardItem())
            self.model.setItem(row, 2, QtGui.QStandardItem())

        self.table_view.setModel(self.model)
        self.table_view.setItemDelegateForColumn(1, self.button_delegate)
        self.table_view.setItemDelegateForColumn(2, self.progress_delegate)
        self.table_view.resizeColumnsToContents()
        self.table_view.horizontalHeader().setSectionResizeMode(
            QtWidgets.QHeaderView.ResizeMode.Stretch
        )

    def on_button_clicked(self, index):
        model = self.table_view.model()
        progress_index = model.index(index.row(), 2)

        current_state = progress_index.data(QtCore.Qt.ItemDataRole.DisplayRole)

        if current_state is None or current_state == 0:
            model.setData(
                progress_index, "green", QtCore.Qt.ItemDataRole.UserRole
            )
            model.setData(
                progress_index, 1, QtCore.Qt.ItemDataRole.DisplayRole
            )
        else:
            model.setData(
                progress_index, "red", QtCore.Qt.ItemDataRole.UserRole
            )
            model.setData(
                progress_index, 0, QtCore.Qt.ItemDataRole.DisplayRole
            )


if __name__ == "__main__":
    app = QtWidgets.QApplication(sys.argv)
    window = MainWindow()
    window.show()
    sys.exit(app.exec())
When you run this, each row has a "Start/Stop" button. Clicking it the first time turns the progress bar green (running). Clicking again turns it red (stopped). Each subsequent click toggles between the two states.
For an in-depth guide to building Python GUIs with PySide6 see my book, Create GUI Applications with Python & Qt6.
November 04, 2026 06:00 AM UTC
Graham Dumpleton
Twenty years of mod_wsgi, and what comes next
Twenty years ago, around this time, the idea for mod_wsgi was taking shape in my head. The coding started in December 2006. I had no idea back then that it would end up being something I would still be maintaining two decades later, or that it would become the thing many people in the Python community know me for.
People tend to either love mod_wsgi or hate it. Those who love it value that it is solid and has been around forever, and that it just keeps running once you have it set up. Those who hate it usually aren't really complaining about mod_wsgi itself, but about Apache httpd. Configuring Apache was never anyone's idea of fun, and mod_wsgi inherits all of that baggage simply by being an Apache module.
Why Apache in the first place
It is easy to forget what the landscape looked like back then. The WSGI specification existed, but there was no standard, well trodden way of hosting a WSGI application in production. The options were things like CGI, FastCGI or SCGI bridges, or mod_python, which wasn't built around WSGI and came with its own set of problems. Nginx wasn't on the radar of most people outside of Russia, and Python WSGI servers like gunicorn were still years away.
What did exist was Apache, and it was everywhere. Pretty much any hosting environment you could get your hands on had Apache installed. Building on top of Apache meant that mod_wsgi could provide a standardised way of hosting Python web applications on infrastructure people already had, and that is the hole it ended up filling.
Living within Apache's rules
The catch is that Apache httpd is even older than mod_wsgi, and its architecture was never designed with something like mod_wsgi in mind. This is particularly the case with daemon mode, where the Python web application runs in separate processes from the Apache worker processes handling incoming requests.
Apache owns the lifecycle of all its child processes. The daemon processes mod_wsgi uses are created by the Apache parent process, and so are bound by how Apache decides to start, stop and restart processes. The number of daemon processes is fixed by the configuration, and changing anything means restarting Apache. If you wanted a process manager that could make smarter decisions about the Python application, such as scaling the number of processes up or down based on load, or rolling out a new version of the application without disrupting requests in flight, you were fighting Apache to do it.
So mod_wsgi did the best it could within those constraints. Over the years there was a long list of things I would have loved to add, but which were never going to be practical while sitting inside Apache. Some of them I tried to approximate, others I simply had to let go.
Why revisit this now
Being on sabbatical, and with full retirement looking more likely, I have the time to come back to the problem and think about how I would do it if I wasn't bound by Apache.
To be frank though, if I had to sit down and write such a system from scratch myself, I wouldn't even try. The scale of what is involved is large, and the coding is the part I find a chore these days. What makes the difference is AI coding tools. They have become good enough at taking an idea and turning it into a working implementation that the coding is no longer my problem. Instead I get to focus on the parts I actually enjoy, which is the architecture, the design, and working out which features are worth having and how they should behave.
Working at that level has turned out to be a lot of fun. I can go from an idea to seeing it work far quicker than I ever could before, and that gratification of seeing an idea come to life is, I suspect, what most of us got into this for in the first place.
So what is Muru
With the free time to think the problem through properly, and AI tools able to take on the heavy lifting of writing the code, I decided to embark on creating a new and more modern system for hosting Python web applications. That system is called Muru.
Muru isn't an Apache module, and it isn't just another WSGI server to run behind something else. The aim is to take everything I learned from twenty years of mod_wsgi, and from watching how people actually deploy Python web applications, and build something that covers the whole job of running a Python web application, from your laptop through to production.
Despite where it comes from, Muru isn't limited to WSGI either. It can also host ASGI applications, as well as gRPC services. More than that, these can be mixed together in the one application, rather than needing to be run as separate deployments. Extensions are available to hand off requests from WSGI to ASGI and vice versa, which makes it easy to bring things like websockets to an existing WSGI application without having to rewrite it.
Beyond what it can host, part of what Muru sets out to do is simply bring in good practice. There are a lot of things that every production deployment needs, but which are left as an exercise for the user to get right. Things like how a new version of an application gets rolled out, how requests get routed to it, how it reports whether it is healthy, and how it restarts without dropping requests. Most people end up reinventing these badly, or not doing them at all. Muru tries to make them the default rather than something you have to bolt on.
The other part, and the bit I think makes Muru different, is that it is built with an intimate knowledge of what Python web applications need. A generic process manager or container platform treats your application as a black box. It can see whether the process is running and how much CPU and memory it is using, but not much more. Python web applications have their own quirks though, whether that is the GIL and how it shapes the choice between processes and threads, how long an application can take to import and become ready, or how memory use can creep up over time. Muru is designed around those realities rather than ignoring them.
That knowledge also extends to metrics. A Python web application can tell you a lot about how it is coping, such as how busy its request handler threads are, how long requests are waiting before being handled, and whether a process is getting into trouble. The idea with Muru is that these aren't just numbers to put on a dashboard after the fact, but signals that feed back into how the application is hosted, driving decisions about capacity, process management and routing.
Muru is still very much in development. I am not going to point to where it lives just yet. If you go looking and find it, that is fine, but at this stage I would rather it was only people with a real need for something like it who were poking at it.
Where these posts are heading
Rather than try and describe everything in one go, I intend to write a series of posts working through what Muru can do. Part of the reason for doing this is to get my own ideas out there about what hosting a Python web application should involve. I am also hoping it might prompt others to share what they think is missing from the current options, because hearing about the problems other people are running into would help me work out where Muru should go next.
As for what the posts will cover, I plan to start with local development, since the same tool you use to host the application in production is also there to help while you are developing it. From there I will look at deploying to a host or virtual machine, including how Muru manages deployments of new versions and handles routing of requests. Further along there is running Muru in containers and on Kubernetes, and all the bits those platforms need from an application for it to behave well, such as health probes, metrics, and draining requests on shutdown.
A word about AI
As has become usual for me of late, a small disclaimer. Muru is being built with heavy use of AI coding tools. I am the one deciding what it should do and how it should be structured, and I am reviewing and steering the result, but most of the code was written by an AI.
I know some people are firmly opposed to AI-written software, and I am not going to argue with that position. If AI involvement rules Muru out for you, then Muru is not for you, and that is okay.
What comes next
Twenty years is a long time to have been working on the one problem, and it seems I am still not done with it. I am not abandoning mod_wsgi, but Muru is my chance to finally build the things I always wanted to and never could. Fingers crossed it turns out to be as useful to others as I hope it will be.
November 04, 2026 12:00 AM UTC
November 03, 2026
TestDriven.io
Taking Website Screenshots with Django, Celery, and Playwright
This tutorial looks at how to build a Django app that takes website screenshots using Playwright and Celery.
November 03, 2026 10:28 PM UTC
Talk Python to Me
#568: Cloudflare Python Workers
Where does your Python code actually run? A server in Virginia? A container in Frankfurt? Pyodide put Python into the browser. Cloudflare put the browser into the server. Combine the two and you get Python Workers, now generally available. My guests are Hood Chatham, Gyeongjae Choi, and Dominik Picheta from Cloudflare. Hood and Gyeongjae maintain Pyodide. Dominik got Python running in Cloudflare Workers in the first place. Your FastAPI app ships as plain Python files. It runs on CPython compiled to WebAssembly, inside V8, at over 350 locations worldwide.<br/> <br/> <strong>Episode sponsors</strong><br/> <br/> <a href='https://talkpython.fm/talk-python-membership-inner-circle'>Talk Python Membership</a><br> <a href='https://talkpython.fm/talk-python-membership-continue-conversation'>Talk Python Membership</a><br> <a href='https://talkpython.fm/training'>Talk Python Courses</a><br/> <br/> <h2 class="links-heading mb-4">Links from the show</h2> <div><strong>Guests</strong><br/> <strong>Gyeongjae Choi</strong>: <a href="https://www.linkedin.com/in/gyeongjae-choi-b259b0163?featured_on=talkpython" target="_blank" >linkedin.com</a><br/> <strong>Hood Chatham</strong><br/> <strong>Dominik Picheta</strong><br/> <br/> <strong>Pyodide</strong>: <a href="https://pyodide.com?featured_on=talkpython" target="_blank" >pyodide.com</a><br/> <strong>Python Everywhere: The State of Python on WebAssembly - Hood Chatham, Gyeongjae Choi</strong>: <a href="https://www.youtube.com/watch?v=HklunTc9giA" target="_blank" >www.youtube.com</a><br/> <strong>PEP 783</strong>: <a href="https://peps.python.org/pep-0783/?featured_on=talkpython" target="_blank" >peps.python.org</a><br/> <strong>D1 Databases</strong>: <a href="https://www.cloudflare.com/products/d1/?featured_on=talkpython" target="_blank" >www.cloudflare.com</a><br/> <strong>Hyperdrive</strong>: <a href="https://www.cloudflare.com/products/hyperdrive/?featured_on=talkpython" target="_blank" >www.cloudflare.com</a><br/> <strong>R2 Object Storage</strong>: <a href="https://www.cloudflare.com/products/r2/?featured_on=talkpython" target="_blank" >www.cloudflare.com</a><br/> <strong>Queues</strong>: <a href="https://developers.cloudflare.com/queues/?featured_on=talkpython" target="_blank" >developers.cloudflare.com</a><br/> <strong>AI</strong>: <a href="https://www.cloudflare.com/products/workers-ai/?featured_on=talkpython" target="_blank" >www.cloudflare.com</a><br/> <strong>now generally available</strong>: <a href="https://blog.cloudflare.com/python-workers-ga/?featured_on=talkpython" target="_blank" >blog.cloudflare.com</a><br/> <strong>Memory Snapshots for CPython (Python Language Summit 2026\)</strong>: <a href="https://blog.python.org/2026/09/language-summit-2026-memory-snapshots/?featured_on=talkpython" target="_blank" >blog.python.org</a><br/> <strong>Cloudflare Worker Limits</strong>: <a href="https://developers.cloudflare.com/workers/platform/limits/?featured_on=talkpython" target="_blank" >developers.cloudflare.com</a><br/> <strong>Litestream</strong>: <a href="https://litestream.io?featured_on=talkpython" target="_blank" >litestream.io</a><br/> <strong>workerd</strong>: <a href="https://github.com/cloudflare/workerd?featured_on=talkpython" target="_blank" >github.com</a><br/> <strong>Are we PEP 783 yet?</strong>: <a href="https://pyodide.github.io/are-we-pep783-yet/?featured_on=talkpython" target="_blank" >pyodide.github.io</a><br/> <strong>The Birth & Death of JavaScript</strong>: <a href="https://www.destroyallsoftware.com/talks/the-birth-and-death-of-javascript?featured_on=talkpython" target="_blank" >www.destroyallsoftware.com</a><br/> <br/> <strong>Watch this episode on YouTube</strong>: <a href="https://www.youtube.com/watch?v=Kgh9-p7yb9A" target="_blank" >youtube.com</a><br/> <strong>Episode #568 deep-dive</strong>: <a href="https://talkpython.fm/episodes/show/568/cloudflare-python-workers#takeaways-anchor" target="_blank" >talkpython.fm/568</a><br/> <strong>Episode transcripts</strong>: <a href="https://talkpython.fm/episodes/transcript/568/cloudflare-python-workers" target="_blank" >talkpython.fm</a><br/> <br/> <strong>Theme Song: Developer Rap</strong><br/> <strong>🥁 Served in a Flask 🎸</strong>: <a href="https://talkpython.fm/flasksong" target="_blank" >talkpython.fm/flasksong</a><br/> <br/> <strong>---== Don't be a stranger ==---</strong><br/> <strong>YouTube</strong>: <a href="https://talkpython.fm/youtube" target="_blank" ><i class="fa-brands fa-youtube"></i> youtube.com/@talkpython</a><br/> <br/> <strong>Bluesky</strong>: <a href="https://bsky.app/profile/talkpython.fm" target="_blank" >@talkpython.fm</a><br/> <strong>Mastodon</strong>: <a href="https://fosstodon.org/web/@talkpython" target="_blank" ><i class="fa-brands fa-mastodon"></i> @talkpython@fosstodon.org</a><br/> <strong>X.com</strong>: <a href="https://x.com/talkpython" target="_blank" ><i class="fa-brands fa-twitter"></i> @talkpython</a><br/> <br/> <strong>Michael on Bluesky</strong>: <a href="https://bsky.app/profile/mkennedy.codes?featured_on=talkpython" target="_blank" >@mkennedy.codes</a><br/> <strong>Michael on Mastodon</strong>: <a href="https://fosstodon.org/web/@mkennedy" target="_blank" ><i class="fa-brands fa-mastodon"></i> @mkennedy@fosstodon.org</a><br/> <strong>Michael on X.com</strong>: <a href="https://x.com/mkennedy?featured_on=talkpython" target="_blank" ><i class="fa-brands fa-twitter"></i> @mkennedy</a><br/></div>
November 03, 2026 08:33 PM UTC
PyCoder’s Weekly
Issue #759: Pillow Flaw, JIT Removed, Security, and More (2026-11-03)
#759 – NOVEMBER 3, 2026
View in Browser »

Critical Flaw in Pillow Allows Code Execution
A critical flaw was found in Pillow, the popular image library. A specially crafted EPS file could result in code execution. Pillow 13.0.0 fixed this and several other issues. This post describes the release and exploit.
SWATI KHANDELWAI
Python’s Experimental JIT to Be Removed
PEP 836 has been withdrawn and the experimental JIT is to be removed from CPython’s main branch. This article talks about the JIT’s journey and what still may be in store.
JOE BROCKMEIER
CodeAF: 78% on DeepSWE with an Open Model
With DeepSeek V4.1 Flash, CodeAF fixed 88 of 113 GitHub issues on DeepSWE. Against Codex and eight other harnesses on one open model, it ranked #1 at the lowest cost per fix. CodeAF is an open-source coding harness built for open models, and works with closed models too. Star on GitHub
AGENTFIELD sponsor
Supply Chain Security for the Age of AI-Speed Exploits
Learn Python supply chain security as AI speeds up attacks: what the LiteLLM backdoor teaches, how to check your setup, and habits that last.
REAL PYTHON
Move Past the Chat Window With Codex CLI
If you’re still pasting code and tracebacks into a chat, let an agent work inside your project instead. Codex CLI runs in your terminal, reads your files, runs your tests, and follows the project rules you write in an AGENTS.md file. Over two live days on November 14–15, you’ll build a full Python CLI app this way, from an empty directory to GitHub.
REAL PYTHON
Articles & Tutorials
Google Adopts Pyrefly for Typechecking
Python is one of the primary languages at Google, powering everything from machine learning research to developer infrastructure and data pipelines. Replacing previous type-checking infrastructure with Pyrefly provided significant speedups for engineers and agents alike, while substantially reducing build-system compute resources.
GOOGLEBLOG.COM • Shared by anonymous
Polars 2.0: Streaming by Default and Stricter Types
Polars 2.0 makes lazy queries faster without code changes, but its new defaults can affect existing workflows. This article compares Polars 1.x and 2.0, covering streaming performance, spill-to-disk, changes to join ordering, and stricter type checking that catches silent precision loss.
OPENTEAMS.COM • Shared by Khuyen Tran
Django as a Simple Static Site Builder
Combining three libraries: nanodjango, django-nanopages, and django-distill, you can create a static site generator in just a few lines of code. Why learn another tool when you already know Django?
RADIAC
GPT-6.1 Terra Draws a Python Reading a Book
Explore GPT-6.1 Terra’s Python code, turtle drawing, and responses to small tasks that check modern syntax, release knowledge, focused edits, and made-up functions.
REAL PYTHON
Python vs Go: A Practical Comparison for Developers
This article looks at how Python and Go differ, what surveys say about the devs who use them, and what interviews say about the trade-offs between them.
DOMINIKA STANKIEWICZ
Python Typing Survey 2026 Results
This post summarizes the results of the 2026 Python Typing survey. Type hint use changed somewhat, but the choice of type checker has changed sharply.
FACEBOOK
13 Project Ideas for Intermediate Python Developers
Try 13 Python project ideas for intermediate developers. Build web, GUI, and command-line apps that challenge you and make you a better Pythonista.
REAL PYTHON
Three Ways of Storing and Accessing Lots of Images in Python
Compare three ways of storing images in Python, as PNG files on disk, in LMDB, and in HDF5, with timings for reading and writing lots of images.
REAL PYTHON
NumPy Tutorial: Your First Steps Into Data Science in Python
Follow this NumPy tutorial to learn how to create and manipulate arrays in Python and take your first steps into data science.
REAL PYTHON
Python on My Wrist
This blog post talks about reviving PineTime smartwatch running up-to-date MicroPython and wasp-os.
MICHIEL BEIJEN
Tachyon: Sampling Profiling in Python
Learn how to use Tachyon, Python’s sampling profiler.
RODRIGO GIRÃO SERRÃO
Projects & Code
Events
Weekly Real Python Office Hours Q&A (Virtual)
November 4, 2026
REALPYTHON.COM
Canberra Python Meetup
November 5, 2026
MEETUP.COM
Sydney Python User Group (SyPy)
November 5, 2026
SYPY.ORG
PyCon ES 2026
November 6 to November 9, 2026
PYCON.ORG
Python El Salvador Vuelve
November 7, 2026
PYTHON.ORG.SV
PyCon Chile 2026
November 14 to November 16, 2026
PYCON.CL
Happy Pythoning!
This was PyCoder’s Weekly Issue #759.
View in Browser »
[ Subscribe to 🐍 PyCoder’s Weekly 💌 – Get the best Python news, articles, and tutorials delivered to your inbox once a week >> Click here to learn more ]
November 03, 2026 07:30 PM UTC
Django Weblog
Django security releases issued: 6.1.3, 6.0.10, and 5.2.19
In accordance with our security release policy, the Django team is issuing releases for Django 6.1.3, Django 6.0.10, and Django 5.2.19. These releases address the security issues detailed below. We encourage all users of Django to upgrade as soon as possible.
CVE-2026-108147: Potential memory exhaustion in MultiPartParser via base64-encoded file upload
When using django.http.multipartparser.MultiPartParser, multipart uploads
with Content-Transfer-Encoding: base64 could be buffered entirely in memory,
regardless of FILE_UPLOAD_MAX_MEMORY_SIZE, before being passed to upload
handlers, potentially consuming excessive memory.
This issue has severity "low" according to the Django Security Policy.
Thanks to Ignacy Kujawa for the report.
CVE-2026-111211: Potential log injection via unescaped geometry form values
django.contrib.gis.forms.GeometryField and its widgets logged invalid
submitted values directly, allowing control characters (e.g. newlines or ANSI
escape sequences) to be written unescaped into logs. This could enable log
injection or forgery, letting attackers manipulate log appearance or
structure, especially in logs processed by external systems or viewed in
terminals.
This issue has severity "low" according to the Django Security Policy.
Thanks to Aaron chen for the report.
CVE-2026-111362: Server-side request forgery via crs member of GeoJSON geometries
Earlier versions of the GeoJSON spec allowed specifying a coordinate reference system (CRS) by URL. Since GDAL still resolves these URLs, any validation, save, or query path where a geometry is instantiated from user input allowed an attacker to submit a malicious CRS that would make a network request as the Django process user, or read a file, or both.
Lookups against spatial fields, the GeometryField form field, and GEOSGeometry now reject GeoJSON geometries with CRS references to external resources. The DataSource and
LayerMapping utilities for loading trusted data continue to accept these values.
This issue has severity "moderate" according to the Django Security Policy.
Thanks to Submersion Security Research Team for the report.
CVE-2026-113593: Potential exposure of private data via empty and missing Vary headers
UpdateCacheMiddleware and cache_page() generated the same cache key
for a request that omitted a header listed in the response's Vary header
and a request that sent that header with an empty value. As a result, a
response cached for one of these requests could be served to the other, which
could lead to the exposure of private data.
Cache keys now distinguish between absent and empty header values, as required by RFC 9111#section-4.1.
Responses previously cached for requests that omitted a header listed in
Vary will no longer be matched, and will be cached again on the next
request.
This issue has severity "low" according to the Django security policy.
Thanks to Andrew Gonzalez for the report.
CVE-2026-113733: Password hash disclosure to "view only" admin users with custom user models
Admin users with the view (but not change) permission to a user model were
displayed the entire password hash when the model was not AUTH_USER_MODEL,
or when AUTH_USER_MODEL inherited its password field from a concrete
parent model through multi-table inheritance.
This issue has severity "low" according to the Django Security Policy.
Thanks to Aaron chen for the report.
CVE-2026-114582: Server-side request forgery via SpatialReference string input
SpatialReference passed string input to GDAL,
which by default resolves URLs and reads files. This behavior was not
documented by Django. Other affected methods included
GEOSGeometry.transform(), OGRGeometry.transform(), GDALRaster.transform(),
the srs setter of OGRGeometry, and the srs and srid setters of GDALRaster.
A URL or file path reaching any of these would issue an outbound request or
read a file as the Django process user. The attack vectors could be combined to
reveal local file contents by observing outbound requests.
SpatialReference now disables network and file access when parsing string
input on GDAL 3.9 and later. As a consequence, file paths and URLs are no
longer accepted as SpatialReference inputs. Dictionary references using the
DICT: prefix, including those prefixed with ESRI::, are rejected on all
GDAL versions.
Full protection requires GDAL 3.9 or later. Integer SRIDs are looked up
directly in the EPSG database, so prefer them when the input is untrusted. Or,
if strings must be used on lower GDAL versions, compare to an allow list. The
new gis.W001 system check warns when the installed version of GDAL is not
at least 3.9.
This issue has severity "low" according to the Django security policy.
Thanks to Adraca for the report.
Affected supported versions
- Django main
- Django 6.1
- Django 6.0
- Django 5.2
Resolution
Patches to resolve the issue have been applied to Django's main, 6.1, 6.0, and 5.2 branches. The patches may be obtained from the following changesets.
CVE-2026-108147: Potential memory exhaustion in MultiPartParser via base64-encoded file upload
- On the main branch
- On the 6.1 branch
- On the 6.0 branch
- On the 5.2 branch
CVE-2026-111211: Potential log injection via unescaped geometry form values
- On the main branch
- On the 6.1 branch
- On the 6.0 branch
- On the 5.2 branch
CVE-2026-111362: Server-side request forgery via crs member of GeoJSON geometries
- On the main branch
- On the 6.1 branch
- On the 6.0 branch
- On the 5.2 branch
CVE-2026-113593: Potential exposure of private data via empty and missing Vary headers
- On the main branch
- On the 6.1 branch
- On the 6.0 branch
- On the 5.2 branch
CVE-2026-113733: Password hash disclosure to "view only" admin users with custom user models
- On the main branch
- On the 6.1 branch
- On the 6.0 branch
CVE-2026-114582: Server-side request forgery via SpatialReference string input
- On the main branch
- On the 6.1 branch
- On the 6.0 branch
- On the 5.2 branch
The following releases have been issued
- Django 6.1.3 (tarball | checksums)
- Django 6.0.10 (tarball | checksums)
- Django 5.2.19 (tarball | checksums)
The PGP key ID used for this release is Jacob Walls: 131403F4D16D8DC7
General notes regarding security reporting
As always, we ask that potential security issues be reported via private email
to security@djangoproject.com, and not via Django's Trac instance, nor via
the Django Forum. Please see
our security policies for further
information.
November 03, 2026 03:30 PM UTC
Python Software Foundation
Announcing new Security Developer at the PSF
We’re excited to announce that Brett Smith is joining the Python Software Foundation as a Security Developer.
Brett will be working closely with Seth Larson, Security Developer in Residence, and Mike Fiedler, PyPI Safety and Security Engineer, on the PSF’s security team to address the increasingly demanding scale of security response for the Python ecosystem. We’re grateful to Anthropic for their generous support, which has made the critical new Security Developer role possible.
 |
Security Response at Ecosystem Scale
At PyCon US 2026, Seth Larson and Mike Fiedler presented that 2026 was the “year of more” when it comes to security: the Python Security Response Team (PSRT) is processing 3-4× the volume of reports and CVEs for Python and pip compared to just a year ago, and the amount of malware published and removed from the Python Package Index (PyPI) is up 60% compared to last year. The complexity of securing the vast Python ecosystem is growing along with the scale, particularly in the face of the evolving role of AI in both security risks and security response. Providing prompt security response services and innovating to prevent future threats at the scale of an ecosystem like Python is more difficult now than ever before.
Brett’s addition to the PSF positions us to better meet this growing challenge. Having Brett on the team will both build capacity for security work the PSF already does and enable new, proactive work: He’ll help us keep pace with critical ongoing work such as vulnerability remediation, providing vulnerability data as a CVE Numbering Authority, and removing malware from PyPI. He’ll also give the team bandwidth for new projects such as scaling PyPI’s autonomous quarantine program to reduce manual effort on malware remediation and streamlining processes for the PSRT to handle the new vulnerability report volume. Stay tuned for what’s coming next on the PSF security roadmap by subscribing to the PSF blog or newsletter.
About the Python Software Foundation
The Python Software Foundation (PSF) is a non-profit whose mission is to promote, protect, and advance the Python programming language, and to support and facilitate the growth of a diverse and international community of Python programmers. The PSF supports the Python community using corporate sponsorships, grants, and donations. Are you interested in sponsoring or donating to the PSF so it can continue supporting Python and its community? Check out our sponsorship program, donate directly here, or contact our team!
November 03, 2026 08:29 AM UTC
Tryton News
Tryton News November 2026
After the Tryton 8.2 release landed in October, the community turned to the work that follows up. The product category search responds to parent categories again, and the documentation got some improvements.
For an in depth overview of the Tryton issues please take a look at our issue tracker or see the issues and merge requests filtered by label.
Changes for the User
Stock, Production and Shipments
When you search for a product category by name, the parent categories are matched as well.
New Documentation
The stock documentation now describes the procedure for setting lots on assigned moves.
The sale credit limit module documentation has been refreshed to match the latest behaviour and configuration options.
The move grouping wizard now has its own section in the accounting documentation.
New Releases
We released bug fixes for the recently released 8.2 minor series and the currently maintained long term support series 8.0, 7.8, and 7.0.
Changes for Implementers and Developers
The product category now extends the tree() domain instead of overriding it. Overriding could mask the contribution of the tree() mixin to search_rec_name, so anyone who reuses the search override pattern should leave the tree() clause extension in place.
The party replacement now takes an optional WHERE clause to restrict the rows that are updated. The clause is provided by a hook on the model, so developers can keep certain rows (such as moves that have already been voided) untouched while the rest of the party field is rewritten.
Initial draft powered by Minimax-M3. Curated and finalized by human hands.
1 post - 1 participant
November 03, 2026 07:00 AM UTC
Python Bytes
#503 It’s not 85% HTML
<strong>Topics covered in this episode:</strong><br> <ul> <li><strong><a href="https://mkennedy.codes/posts/your-github-language-bar-is-lying-and-how-to-fix-it?featured_on=pythonbytes">Your GitHub language bar is lying (how to fix it)</a></strong></li> <li><strong><a href="https://engineering.fb.com/2026/10/27/developer-tools/python-typing-survey-2026-ai-tools-checker-landscape/?featured_on=pythonbytes">Python Typing Survey 2026: developers mix type checkers, and AI is writing the hints</a></strong></li> <li><strong><a href="https://www.flaskvibe.com/?featured_on=pythonbytes">Flask Vibe - Build Apps You Can Understand</a></strong></li> <li><strong><a href="https://tildeweb.nl/~michiel/python-on-my-wrist.html?featured_on=pythonbytes">Python on my wrist: MicroPython on a PineTime</a></strong></li> <li><strong>Extras</strong></li> <li><strong>Joke</strong></li> </ul><a href='https://www.youtube.com/watch?v=o63T94KiWng' style='font-weight: bold;' data-umami-event="Livestream-Past" data-umami-event-episode="503">Watch on YouTube</a><br> <p><strong>About the show</strong></p> <p>Sponsored by us! Support our work through:</p> <ul> <li>Our <a href="https://training.talkpython.fm/?featured_on=pythonbytes"><strong>courses at Talk Python</strong></a></li> <li>Consulting from <a href="https://sixfeetup.com/?featured_on=pythonbytes"><strong>Six Feet Up</strong></a> <strong>Connect with the hosts</strong></li> <li>Michael: <a href="https://fosstodon.org/@mkennedy">Mastodon</a> / <a href="https://bsky.app/profile/mkennedy.codes?featured_on=pythonbytes">BlueSky</a> / <a href="https://x.com/mkennedy?featured_on=pythonbytes">X</a> / <a href="https://www.linkedin.com/in/mkennedy/?featured_on=pythonbytes">LinkedIn</a></li> <li>Calvin: <a href="https://sixfeetup.social/@calvin?featured_on=pythonbytes">Mastodon</a> / <a href="https://bsky.app/profile/calvinhp.com?featured_on=pythonbytes">BlueSky</a> / <a href="https://x.com/calvinhp?featured_on=pythonbytes">X</a> / <a href="https://www.linkedin.com/in/calvinhp/?featured_on=pythonbytes">LinkedIn</a></li> <li>Show: <a href="https://fosstodon.org/@pythonbytes">Mastodon</a> / <a href="https://bsky.app/profile/pythonbytes.fm">BlueSky</a> / <a href="https://x.com/PythonBytes?featured_on=pythonbytes">X</a> Join us on YouTube at <a href="https://pythonbytes.fm/stream/live"><strong>pythonbytes.fm/live</strong></a> to be part of the audience. Usually <strong>Tuesday at 7am PT</strong>. Older video versions available there too. Finally, if you want an artisanal, hand-crafted digest of every week of the show notes in email form? Add your name and email to <a href="https://pythonbytes.fm/friends-of-the-show">our friends of the show list</a>, we'll never share it.</li> </ul> <p><strong>Michael #1:</strong> <a href="https://mkennedy.codes/posts/your-github-language-bar-is-lying-and-how-to-fix-it?featured_on=pythonbytes">Your GitHub language bar is lying (how to fix it)</a></p> <p>GitHub's language bar comes from Linguist, which counts every tracked byte in the repo. Michael's chameleon-rs project read as 75.5% HTML because committed docs-site output and test suites outweighed the Rust engine. Three .gitattributes attributes changed the story: linguist-generated for build output, linguist-vendored for an upstream test suite, and linguist-detectable=false for tests and benchmarks on both sides. The bar now shows the real mix, roughly 62% Rust and 38% Python.</p> <ul> <li>That bar is one of the first things people see on your repo; if generated files skew it, a few lines of .gitattributes tell the truth.</li> <li>The bar is byte-proportional, so a 9 MB committed docs build can make a Rust project read as mostly HTML</li> <li>linguist-generated hides build output and collapses those diffs in pull requests too</li> <li>linguist-vendored covers copied-in code; linguist-detectable=false drops anything from the stats</li> <li>chameleon-rs went from 75.5% HTML to roughly 62% Rust and 38% Python after a few lines of config</li> <li>Tests and benchmarks were excluded symmetrically, on both the Rust and Python sides, so neither skews the ratio</li> <li>Check patterns before pushing with git check-attr; GitHub recalculates a few minutes after the push</li> </ul> <p><strong>Calvin #2: <a href="https://engineering.fb.com/2026/10/27/developer-tools/python-typing-survey-2026-ai-tools-checker-landscape/?featured_on=pythonbytes">Python Typing Survey 2026: developers mix type checkers, and AI is writing the hints</a></strong></p> <ul> <li>Meta's 2026 Python Typing Survey results: 1,794 responses, Aug 5 - Sep 2. Pyrefly (Meta), JetBrains, Microsoft and Astral's ty team helped write it.</li> <li>Typing is stable: 85.5% use hints often or always (88.0% in 2024). Which checker people use is not stable.</li> <li>49.9% run two or more checkers (46.0% in 2025), and 83.3% of Pyrefly users also run another one. Speed is the top reason for picking a checker (56.5%).</li> <li>Checkers disagree: 33.3% report inconsistencies between them, rising to 42.7% among multi-checker users.</li> <li>AI is writing the types: 42.5% had AI write hints, and 38.4% say types make AI code more reliable (18.5% last year).</li> <li>29.8% are "not sure" whether types help AI-assisted coding, about 4x the uncertainty on any other benefit.</li> <li>Help sources flipped: Stack Overflow 46.4% to 22.9% and LLM chat 26.0% to 41.7%, 2024 to 2026.</li> <li>Top pain is still missing library types (65.1%; Django, SQLAlchemy, pandas, NumPy). The most-wanted feature is better Callable syntax (45.7%). Raw data zip is linked.</li> </ul> <p><strong>Michael #3:</strong> <a href="https://www.flaskvibe.com/?featured_on=pythonbytes">Flask Vibe - Build Apps You Can Understand</a></p> <p>Flask Vibe is a new tutorial site from Frederick Tubiermont, a developer who started coding at 47 and builds with Flask, PostgreSQL, raw SQL, and vanilla JS. The pitch: AI assistants generate more reliable, easier-to-verify code when the stack has no build step, no ORM, and no hydration. It ships a manifesto, tutorials on modular vanilla JS and AI-friendly coding patterns, and a Flask plus psycopg2 CRUD walkthrough.</p> <ul> <li>For vibe coders burned by Next.js defaults on Lovable or Replit, this is a concrete, opinionated case that simpler Python stacks pair better with AI-generated code.</li> <li>Claims a structural 1.8x LCP win over Next.js on the same dashboard app: 905ms vs 1.66s, both scoring Lighthouse 100</li> <li>Tutorials cover modular vanilla JS, AI-friendly coding patterns, and Flask CRUD with raw psycopg2 SQL and no ORM</li> <li>Creator started Python at 47 in 2022 and runs the site on the stack it teaches; the homepage is 42 KB with Lighthouse 100</li> <li>Solo London-based project (adsyme Ltd), launched via an r/flask self-post in February 2026; early, opinionated, and the benchmark leans on one self-run comparison with its methodology published on site</li> </ul> <p><strong>Calvin #4: <a href="https://tildeweb.nl/~michiel/python-on-my-wrist.html?featured_on=pythonbytes">Python on my wrist: MicroPython on a PineTime</a></strong></p> <ul> <li>Michiel (Python Leiden user group) runs MicroPython on a PineTime, Pine64's ~$26 open smartwatch: 64 MHz Cortex-M4, 64 KB RAM, 512 KB flash.</li> <li>He revived wasp-os, a dormant MicroPython watch OS stuck on a 2019 MicroPython fork whose maintainer is asking for new maintainers (issue #536).</li> <li>The build is now one command with uv. Bluetooth flashing uses bleak instead of the deprecated gatttool, cutting update time from over 8 minutes to about 3.5.</li> <li>Free RAM at boot went from 7.1 KB to 12.4 KB by using the flash chip's real 4 KB blocks. He also added a watchdog, plus vibration, touch and I2C dead-battery fixes.</li> <li>His three upstream PRs (frozen native code, PWM, ADC sample time) are merged, so wasp-os now runs on mainline MicroPython. They're targeted for MicroPython 1.30, planned for December.</li> <li>New faces: a Dutch week clock, and an 8-bit pixel clock that draws its digits without any font data and shows a live Unix epoch counter.</li> <li>The Guido app: a 16-color, 80x80 run-length-encoded portrait (photo by Kushal Das, CC BY-SA). All four images total under 12 KB, versus 112 KB for one raw screen.</li> <li>Next up is the PineTime Pro (AMOLED, GPS, dual-core M33), with no release date yet. Code is on the pinetime-upstream-micropython branch of mbeijen/wasp-os.</li> </ul> <p><strong>Extras</strong></p> <p>Calvin:</p> <ul> <li><strong>PyPI now caps version strings at 128 characters —</strong> https://blog.pypi.org/posts/2026-10-23-version-length-limit/</li> <li>Wagtail Space — https://wagtail.org/wagtail-space-2026/</li> </ul> <p>Michael:</p> <ul> <li>Thanks Hugo: <a href="https://hugovk.dev/blog/2026/cybersecurity-awareness/?featured_on=pythonbytes">Lots of Python releases for Cybersecurity Awareness Month</a></li> <li><a href="https://talkpython.fm/meetups/talk-python-in-production-building-your-own-infrastructure?featured_on=pythonbytes">Talk Python Meetup: Talk Python in Production: Building Your Own Infrastructure</a></li> </ul> <p><strong>Joke:</strong> <a href="https://x.com/pr0grammerhum0r/status/1955872046539260290?s=12&featured_on=pythonbytes">Binging red buttons</a></p>
November 03, 2026 03:41 AM UTC
Wingware
Wing Python IDE Version 12.1 - November 3, 2026
Wing 12.1 is now available. It introduces guided autonomous development. You specify the goals, answer questions, and review results. AI agents design and write the code, unit tests, and documentation. Wing keeps you in control. Wing Pro 12.1 now supports Claude Code, Codex, Antigravity, Copilot, Cursor, goose, OpenCode, and other ACP-compatible AI coding agents. It also adds a new Modern look and display themes, graphical revision control history, a redesigned New Project dialog, GitHub integration, and many other improvements.
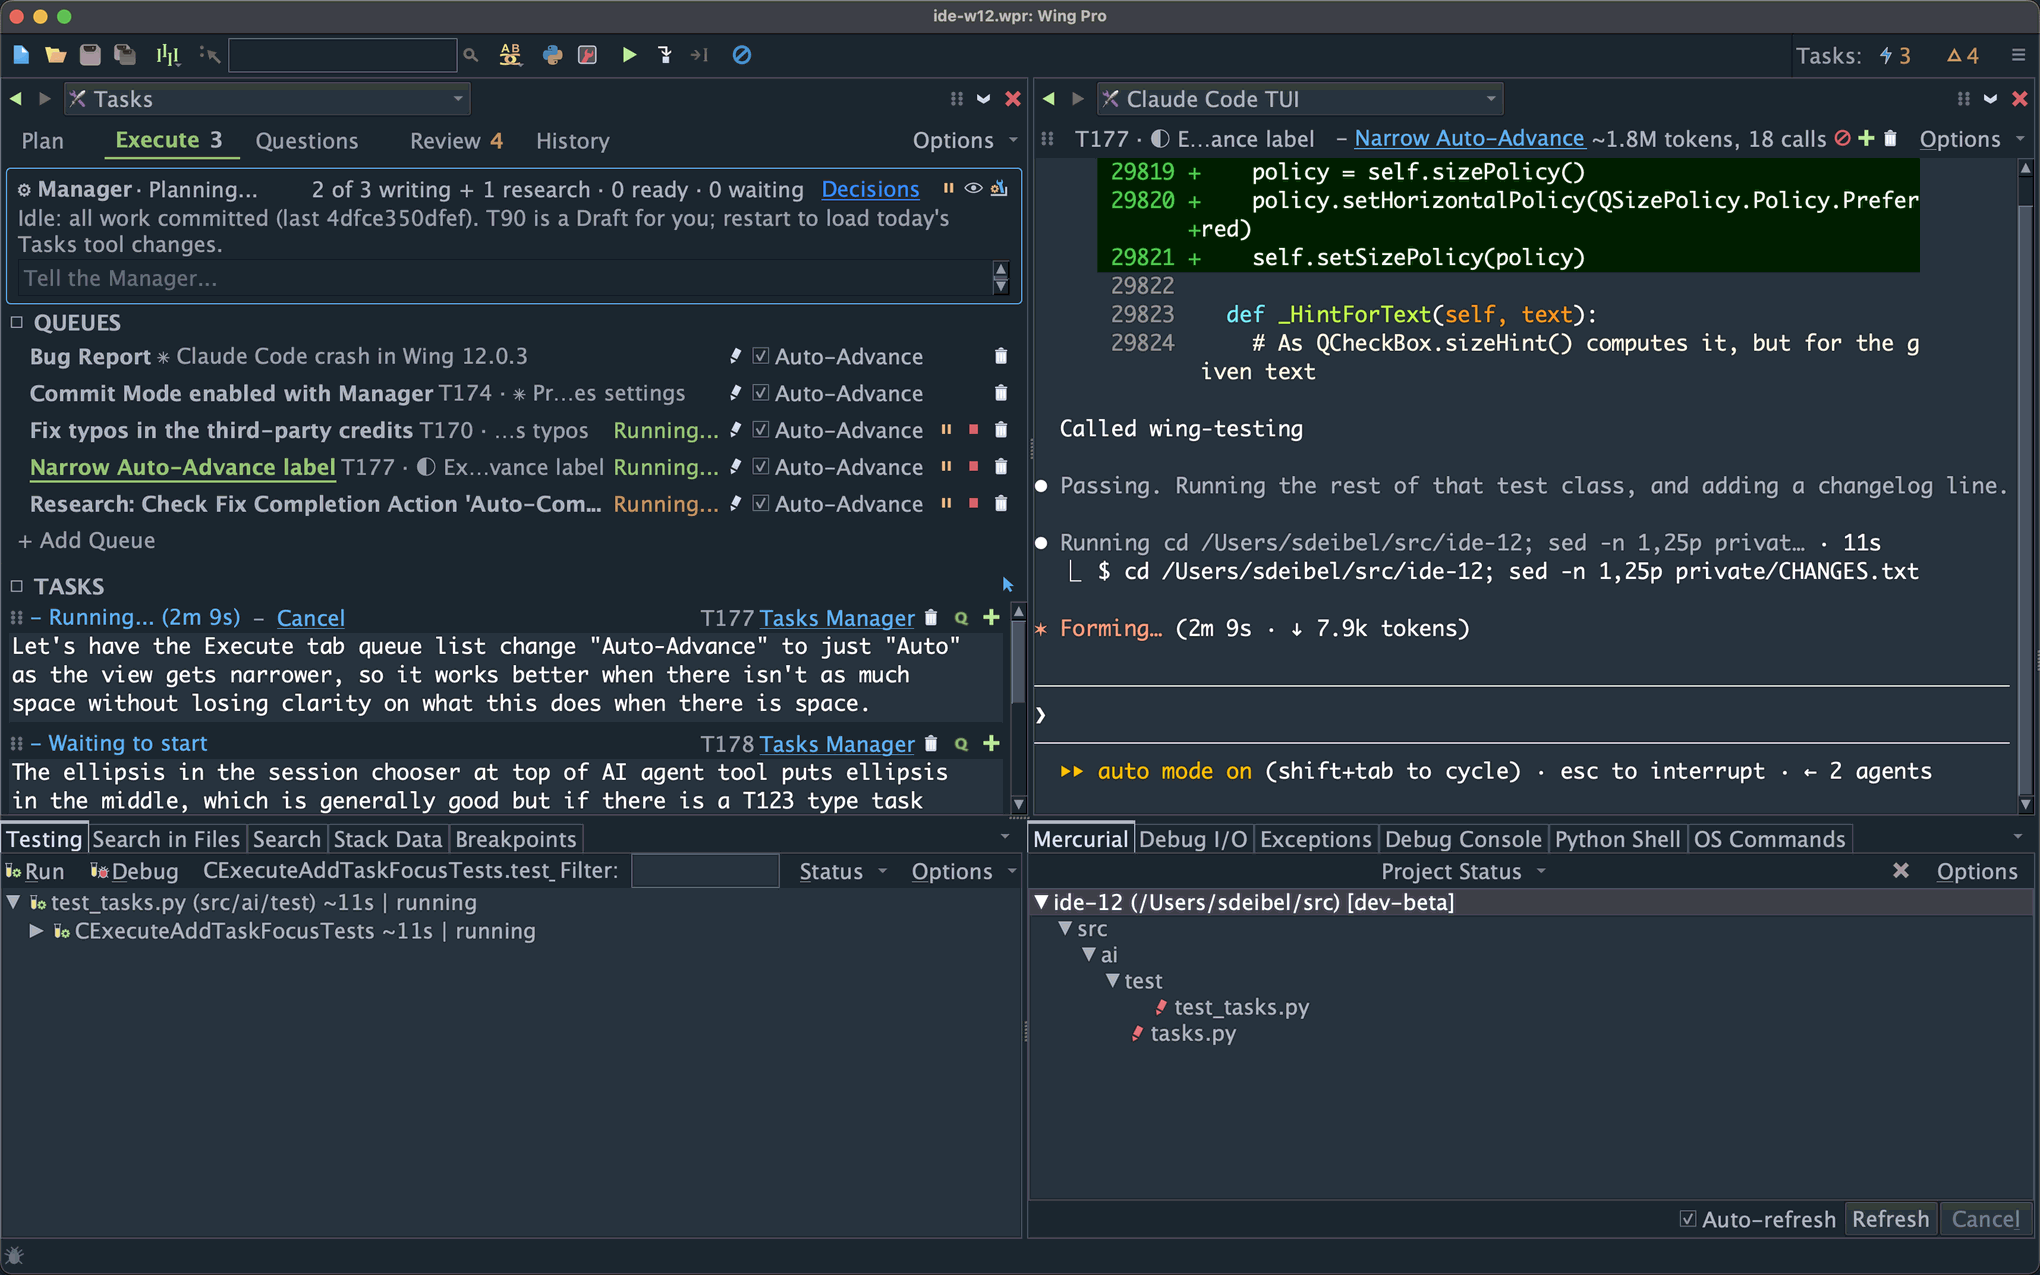
Downloads
Please try it and email us if you find problems or have suggestions!
Wing 12.1.2 -- Full-featured Python IDE with two licensing tiers
Wing 101 12.1.2 -- Free IDE for teaching beginners to program
Wing 12.1 will replace Wing 12.0 when it is installed. You can revert to Wing 12.0 by reinstalling it at any time.
To get started quickly with autonomous development in Wing 12.1, see Getting Started with Autonomous Development.
New in Wing 12.1
Autonomous Development with the Tasks Manager
The new Tasks Manager is an agent that runs the Tasks tool's queues for you, so that development proceeds autonomously under your direction. You write tasks, mark the ones you want started as Ready, and review the results.
The Manager accepts anything from a bug report to a high-level specification for a new software project. It can break down larger tasks into a design and development plan. It decides task order, serializes those that are likely to edit the same files, and runs closely related tasks in shared session context. It can message a running agent to tell it about related work or new insights, or redirect it if it goes astray.
While the Manager is on, tasks run autonomously: Rather than stopping to ask questions or present intermediate results, each works as far as it can and ends with a report of the judgement calls it made along the way, and any questions it has left. A new Questions tab in the Tasks tool collects everything that is waiting for you, so you can provide answers in one place. Follow-up work and problems that agents notice as they run are added to the Plan tab of the Tasks tool as new tasks. The Manager may automatically start found tasks that are closely related to ongoing work; others wait for your review.
You stay in control of which work runs, how much the Manager can do, and how results are reviewed. Every change the Manager makes is listed and can be reverted or revised, even after changes have been committed. You can also talk to the Manager to ask about the status of development or give it special instructions about your development workflow.
Claude Code and Codex are best for autonomous development, since they self-check the safety of commands that they run. Antigravity, Copilot, and Cursor also work but don't implement the same level of safety checks. See AI Agent Safety in the AI Agent-Assisted Development chapter of the Wing manual for details and safety recommendations.
The Manager agent itself and queues in the Tasks tool can each use a different agent. You bring your own subscriptions or API keys for the agents you choose. Wing does not install agents or provide access to models.
Your Choice of AI Agent
Wing 12.1 adds support for other AI agents, now including Claude Code, Codex, Antigravity, Copilot, Cursor, goose, and OpenCode, either using their Textual User Interfaces (TUIs) or the Agent Client Protocol (ACP). AI agents can also set up how your code is run, such as a new program's main entry point, its run arguments, and its Python environment.
Improved User Interface
Modern Look: An optional new Modern look redesigns the toolbar, Preferences dialog, status bar, and tab overflow, and improves the display font. Two new display themes, Night Flight and Solo Flight, have been added. Themes can now incorporate transparent colors, be imported from VS Code, created from a small set of colors, or exported from your current color configuration.
New Project: The New Project dialog has been redesigned as a single page. Its Simple view asks only for the essentials, with a new directory, a virtualenv in the project's .venv, and a git repository as defaults, while All Options shows everything else. Progress is shown as a checklist in the dialog, and a failed step can be retried. Support for uv, Poetry, pipenv, micromamba, and pixi environments has been improved, and Wing offers to install a missing uv, Poetry, or pipenv.
Editor: Editors have a new Show Rendered toggle for Markdown, reST, HTML, SVG, images, and PDF files. The editor's scroll bar shows marks for diffs, search matches, and errors and warnings.
First Start: The first start of Wing is simpler, with a shorter Set Up Wing dialog and a Welcome to Wing window that leads with New Project, Open Folder, and Clone from GitHub. In Wing Pro and Wing Classic, trials now start automatically, with no sign-up, and all the license dialogs have been merged into one.
Improved Revision Control Integration
A new Project Log view in the version control tool shows the whole repository's history for git and Mercurial as a branch graph, with expandable diffs. You can sign in to GitHub, clone from a list of your repositories, and publish a new project to GitHub from New Project. Push Changes in the Project Status view pushes your work, and Merge From Branch on the toolbar merges another branch, in each case with an AI agent resolving any conflicts. The editor can also show annotations with commit message tooltips.
Other Improvements
Tasks Tool: Goals can be set aside for Later, and the Focus mode keeps just one goal open at a time. A new Incoming view collects tasks that agents found or proposed, for quick triage, and the Up Next view on the Execute tab shows what runs next in every queue. New Checklists hold recurring reviews, fixes, and release and deployment steps. A task's committed changes can be reverted, edited, or commented on, and every task has a short ID that links to the task wherever it is cited. Tasks can be sent to Wing on other machines, set up as peers, for example to check or fix something on another OS. Agent sessions and the Tasks Manager continue on their own once a usage limit resets, and Send Note sends a message into a running task's session.
Other Changes: Source analysis is faster and its database is about 30% smaller. Wing offers to install Python if it finds no supported version, and to remove large cache directories left behind by older versions. Accept Debug Connections has moved to Project Properties so it is set per project. Wing 12.1 also includes many bug fixes, particularly for remote development and Docker containers, debugging free-threaded Python on Windows, git worktrees and submodules, non-ASCII text on Windows, unit test discovery, and display themes.
See the change log for details.
Getting Started with Autonomous Development
To get started quickly with autonomous development in Wing 12.1, see Getting Started with Autonomous Development.
If you have questions, please don't hesitate to contact us at support@wingware.com.
November 03, 2026 01:00 AM UTC
November 02, 2026
Doing Math with Python
Code and Solutions Refresh
It's been 11 years, since Doing Math With Python was published. The world of software learning has changed drastically. I hope you are still continuing to learn using books, writing programs and the educators among you, i hope you are doing the same! We must persist.
The book has also ended up being part of the Anthropic copyright settlement. I think it's just a sign of the times and I have become part of the history it appears!
Alright, so, I am going to be doing a bit of a refresh as needed for the various code in the book and solutions to ensure that they are all working with currently latest versions of the Python programming language and the third party packages that's used for the code: sympy, matplotlib and matplotlib_venn.
This will take a while, so here's the software versions i will be working with:
- Python 3.14
- sympy 1.14.0
- matplotlib 3.11.0
- matplotlib_venn 1.1.2
This post is in progress
Chapter 2
Programming challenges
- How does the temperature vary during the day?
One solution I suggested created the two lists with the data manually filled in from the google search results.
The second solution, (file name: nyc_forecast_owm.py) I proposed uses the pyowm package to download the data from open weather map. A reader wrote to me recently that it doesn't work any more.
I took a look at the proposed solution and realized that the API itself has changed, which means the library pyowm had also changed significantly. Not unexpected, since it's been 11 years.
So, this is the new proposed solution to use the real data:
- No need to use a third party package
- Download the CSV file from a new source
- Read the CSV file data to create the graph
I suppose my original intention for asking the reader to use a third party package might have been an attempt to stretch the enterprising reader. However, I don't agree with that intention any more as demonstrating how to use a third party data provider isn't in the scope of the book. So, I am taking it out.
I have created a new web application dedicated for this exercise so that you can download the data in CSV data format - something you learn in the book in Chapter 3 (next chapter).
Reading the CSV file requires the reader to refer to Chapter 3
Here's my proposed updated solution.
First download the data by:
- Visit: https://doingmathwithpython.ai.studio/ and sign up (you don't provide email)
- Next sign in using the username and password
- By default New York is selected and default is also selected to 1 day
- On the top right you can change the temperature units
- Click on Download CSV data

A file will be downloaded which will have the data in the following format:
"Local Date & Time","Temperature"
"2026-11-03 19:00","63.1"
"2026-11-03 22:00","60.3"
"2026-11-04 01:00","58.5"
"2026-11-04 04:00","57.6"
"2026-11-04 07:00","56.5"
"2026-11-04 10:00","63.7"
"2026-11-04 13:00","68.7"
"2026-11-04 16:00","67.6"
Rename the file to weather_New_York_1d_3h.csv and place in the same directory as the program.
Here's the plan of what we will need to do:
- Ignore the first line (CSV header row)
- Read each row, creating one list for the time of the day and a second list for the temperature
- Create our graph
You can find the updated solution here.
November 02, 2026 10:20 PM UTC
Rodrigo Girão Serrão
Migrating to Python 3.15
This practical guide tells you what to pay attention to when migrating to Python 3.15.
This short article walks you through the main things to keep in mind when migrating your code to Python 3.15:
- backwards-compatible features: features released in 3.15 that you can start using because they're backwards compatible
- backwards-incompatible features: features released in 3.15 that you can only start using if your project only targets Python 3.15+
- features that are now 100% supported: features released in 3.11 that are now available in all supported Python versions
15 days of Python 3.15
To celebrate the release of Python 3.15, over the next 15 business days I'll be writing about a new 3.15 feature every day. Explained clearly and with examples so you don't have to sift through the changelog.
Subscribe to receive this free email series:
If you want, you can also check the schedule of the upcoming emails.
3.15 migration guide
When a new Python version is released and you're considering of adopting it, you need to think about three disjoint sets of features in the context of your project. The first two are the set of new features that are backwards-compatible with other Python versions and the set of features that are not backwards-compatible. To understand the third set of features that's relevant, take a look at the following screenshot from python.org:
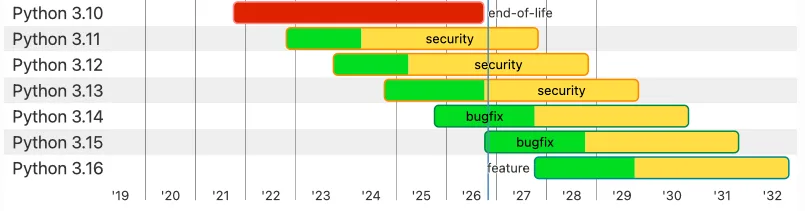 Timeline of the lifecycle of Python versions
With the release of Python 3.15, Python 3.10 officially reached end-of-life and 3.13 entered the security-only stage. This means that Python 3.10 won't be updated anymore and Python 3.13 won't be improved; it'll only receive security updates. If you're working on...
November 02, 2026 03:51 PM UTC
November 01, 2026
Hugo van Kemenade
Lots of Python releases for Cybersecurity Awareness Month
This Cybersecurity Awareness Month, I made seven Python releases, when two were originally planned for October.
Altogether, we made 16 Python releases, when five were originally planned. Of the extra releases, only 3.15.0rc3 was not a security release.
The releases #
- 3.16.0a1
- 3.15.2
- 3.15.1
- 3.15.0
- 3.15.0rc3
- 3.14.10
- 3.14.9
- 3.14.8
- 3.13.18
- 3.13.17
- 3.13.16
- 3.12.16
- 3.12.15
- 3.11.18
- 3.11.17
- 3.10.22
Announcements #
- 1 October: Python 3.10.22, 3.11.17, 3.12.15, 3.13.16 and 3.14.8 are now available!
- 2 October: Python 3.15.0 candidate 3 is here!
- 9 October: Python 3.15.0 (final) is here!
- 13 October: Python 3.16.0 alpha 1 is now available
- 21 October: Python 3.15.1, 3.14.9 and 3.13.17 are out
- 26 October: Python 3.15.2, 3.14.10, 3.13.18, 3.12.16 and 3.11.18 are out
Thanks #
Huge thanks to the Sovereign Tech Agency’s Fellowship for supporting my work on all these releases.
Also thanks to the other release managers Savannah Ostrowski (3.16), Thomas Wouters (3.12 and 3.13) and Pablo Galindo Salgado (3.10 and 3.11), to Ned Deily for the all macOS builds, and to Seth Larson for helping coordinate all this security.
Header image: Computer Security Awareness Day, 1990, from the National Library of Medicine, no known copyright restrictions.
November 01, 2026 08:30 PM UTC
LernerPython blog, from Reuven Lerner
Agentic coding means we’ll need some new abstractions
I’ve been teaching programming (mostly Python) for more than 30 years. But in about a year of coding with AI, I haven’t defined a single data structure or database schema — and I’m accomplishing more, in less time, with fewer bugs, than I ever thought possible. Agentic coding is revolutionary, but it’s part of a larger story that has played out over more than 70 years. In this essay, I look at the evolution of programming languages as successive waves of higher levels of abstraction. I consider what that meant for teaching and learning coding, and how that should influence what we teach as AI becomes the dominant form of programming.
When computers were first invented, there was no such thing as “programming.” Each computer was a special-purpose machine, engineered to solve specific problems. If the problem changed, or if the computer didn’t solve it correctly, you had to make physical changes to the computer. “Debugging” meant cutting wires and soldering parts.
Then some smart people realized that we could separate the computer (the “hardware”) from the instructions and data used to solve the problem (the “software”). No longer did you have to think in terms of wires and logic gates; you could think in terms of instructions and information — verbs and nouns, represented as high and low electrical voltages, 1s and 0s, which we know today as “binary digits,” or “bits.”
Bits were the programmer’s alphabet. Just as we can use letters to write both verbs and nouns in English, programmers could use bits to give the computer instructions and then to also provide the values that the instructions acted on. But programming using bits was hard to learn, not to mention tedious and error-prone.
The power of abstraction
Early programmers quickly adopted the principle of abstraction, combining smaller pieces and processes under a single concept. Abstraction allows us to think and communicate at a higher level. And because our minds can only handle so many things at once, abstraction also allows us to solve larger problems.
Imagine that you’re a traffic planner, trying to understand the ramifications of replacing a traffic light with a traffic circle. You’ll think about the problem in terms of cars. But “car” is an abstraction: If you had to consider all of the parts and processes from each of the vehicles in the intersection, you would never be able to think clearly about the traffic patterns. Communicating your thoughts about those changes would be nearly impossible, because you would be bogged down by low-level details.
The abstraction that programmers adopted became known as assembly language, instructions they could use to control a computer. Programming in assembly was still hard, but it was easier than working with raw binary digits. Moreover, these commands had semantic power, allowing you to think in terms of mathematical operations (e.g., addition and multiplication) and operations within the computer (e.g., moving a value from the CPU to memory). Chip manufacturers competed on the basis of not only speed, but also what high-level instructions their chips supported.
With higher-level programming abstractions, we also got new techniques:
- Repeated lines of code could be replaced with loops, iterating numerous times.
- Code that appeared in multiple locations could be put into subroutines.
- CPUs offered “registers,” a kind of on-chip variable, allowing you to store a value and then refer to it later.
- We saw the beginning of higher-level data structures — integers and floating-point numbers, and even use of integers to represent characters, rather than numbers.
Higher-level languages, higher-level techniques
Why stop with one layer of abstraction, when you could have two? Higher-level languages, such as Fortran, Lisp, PL/I, and (eventually) C, gave us even more semantic power. They looked something like English, requiring translation (“compilation”) into machine code before they could execute. (Fine, Lisp doesn’t exactly look like English.) But the real power of these languages was that both the instructions and the data were using higher-level abstractions than assembly language provided:
- You could define functions, allowing you to add new verbs to the system. Moreover, these functions had human-readable names, giving them semantic power. A function could also be defined on the basis of other functions, giving you an almost limitless number of abstraction layers, each hiding the details of its lower-level parts.
- You could use a wide variety of data structures, many of which hid the underlying bits in which things were stored. You could calculate with integers and floats and work with text (“strings”). You could even combine several such values into an array (all of the same type) or a struct (of mixed types). So you could think in terms of an employee’s salary history, a book’s publication information, or someone’s investment portfolio.
These functions and data structures were ultimately stored as bits in the computer’s memory. But these higher-level functions and data structures allowed you to hide those underlying details, making it possible to tackle increasingly larger problems. Moreover, these higher-level languages lowered the bar to programming even further, allowing a larger number of people to try their hand at solving problems using their computers. However, some of them (e.g., C) still required that we manage the computer’s memory manually.
With these higher-level languages, we started to develop new techniques, including functional and object-oriented programming, which made it easier to create higher-level abstractions for both instructions and data. New languages, such as Smalltalk in the 1970s and C++ in the 1980s, made it possible to use these techniques in our own code.
Python (and friends) arrive on the scene
Starting in the late 1980s and early 1990s, we got a bunch of even higher-level languages, including Tcl, Perl, Python, and Ruby. These languages were originally seen not as full-fledged languages, but rather as providing the “glue” that allowed you to connect different parts of a computer system, as well as automate processes more easily. They were thus dismissed by many serious programmers, called “scripting languages” to emphasize their non-seriousness.
But it turns out that these languages were anything but toys. Yes, their syntax was typically easier to understand than others, and it was easier to jump in and start coding because of their dynamic typing and automatic memory management. But their main advantages were the high-level abstractions they provided:
- Functions: These languages came with a huge number of convenient, expressive functions and methods. And they made it easy to define your own functions, too, with a variety of argument and parameter types.
- Data structures: Even more important, these came with a wide variety of high-level data structures, including powerful and easy-to-use strings, lists (arrays), dicts (hash tables), datetimes, and many more. They typically came with a library of additional data structures, too. And you could define your own data structures, typically using object-oriented programming techniques, with a minimum of syntax and difficulty.
- Third-party add-ons: These languages all arrived at the beginning of the “open source” software movement, which emphasized the benefits of sharing code with others on the Internet. Each language quickly developed its own archive (e.g., Perl’s CPAN and Python’s PyPI) for third-party code contributions. This meant that if you’re trying to solve a problem, and others have solved these problems before, you’ll likely find a solution (or part of a solution) on that third-party archive. These include everything from colorized text (Rich) to data analysis (Pandas and Polars).
These higher-level abstractions — along with supportive communities and easy-to-handle syntax — introduced many newcomers to the world of programming. And they inspired new languages, such as JavaScript, which includes many of the same ideas.
What to teach, what to learn
When I started my CS education in the fall of 1988, most universities taught their intro course in C. To some degree, they did so because it was the most popular language in industry. But they also taught it because C provides a relatively thin layer over assembly code. There was a strong feeling among faculty that to learn programming, you need to start from the lowest-level basics, working your way up to higher-level, more abstract programming languages. They argued that you can only really understand object-oriented and functional programming if you have a solid base of low-level C coding.
But MIT had a very different perspective: They saw programming as a combination of mathematics, philosophy, and linguistics, and taught it that way. Our intro class, known internally as 6.001 and to the rest of the world as Structure and Interpretation of Computer Programs, used Scheme, a version of the Lisp language, which was (unusually) both a very high-level language and a very old one. 6.001 focused on high-level data structures, functions, and how a programming language really works behind the scenes. We learned about variable scoping and bindings, functions as first-class objects, and object-oriented programming.
Never did we think in terms of bits and bytes. Or assembly language. Or memory management. Or what chip we were even using. The focus was on the high-level principles of programming, remaining at that high level of abstraction.
They weren’t trying to say that low-level knowledge is bad or useless. (Another course, 6.004, gave us the chance to learn that topic.) They were, however, trying to say that in the modern world of programming, it’s more important to understand high-level abstractions — how they work, and how to combine them — rather than the underlying machine code.
Nearly 20 years ago, MIT decided to switch away from Scheme for their intro class, to use a language that reflected their high-level approach but was also popular in industry. The language? Python. Thousands of MIT students have thus learned to program with a high-level, dynamic language with rich data structures, first-class functions, support for object-oriented programming, and a warm community of fellow users. Universities around the world have followed MIT’s lead, contributing in no small part to Python’s immense popularity.
How (and what) should AI-native coders learn?
A little more than one year ago, I was convinced that AI could help us code, but that we were a long way off from AI writing code for us. I was wrong; I’ve been using Claude Code and other AI coding systems since January, often for 6-8 hours each day, and I continue to be floored by how much I can get done. I’ve created oodles of functionality for LernerPython, some open-source projects, and a number of things that might turn into online businesses.
For now, I believe that I’m only able to get so much done with Claude Code because of my many decades of programming experience. But my experience here has to do with engineering systems — understanding what the different parts of my program need to do, how to separate them, how to put in guardrails so that I can be sure the software works now and in the future, among other things. I haven’t once modeled a data structure, created a new class, defined a database schema, or implemented a login system, although I have approved specs authored (and then implemented) by Claude Code.
This feels weird. And satisfying. And raises numerous questions about what we should be teaching the next generation of programmers.
I’m convinced that we’re seeing the birth of a new, higher level of abstraction. Just as Python developers don’t need to worry about what instructions are supported by their computer’s chipset, AI-native programmers — people who learn to code through AI, rather than adding AI to skills they already have — don’t need to learn about integers vs. floats, strings vs. bytestrings, or even lists vs. dictionaries, at least not at the beginning. What we long regarded as high-level data structures are now below the abstraction barrier, irrelevant to many coders until they decide to peek behind the curtain.
For now, I still believe that learning to code the old-fashioned way, getting exposed to data structures, functions, and other techniques, is useful. But within a few years, you’ll be able to have a successful coding career without knowing how to implement a dictionary or what “hashable” even means.
The best universities will teach these topics, and the best coders will learn them, because understanding the underlying layers, breaking through the abstraction barriers, can inform and influence your thinking. But just as you can get a coding job in 2026 without knowing the ins and outs of how an operating system works, or how much data your CPU can retrieve in a single clock cycle, you’ll be able to get a coding job in 2036 without knowing the ins and outs of how a programming language works.
Am I arguing against my own courses and products? Not at all: My courses are for people who want deep understanding, exercises, and a chance to ask questions during live office hours. And I still think that knowing Python and Pandas is a great asset in today’s world. I’m adding office hours and courses about AI, which I see as complementary to the existing content, rather than replacing it.
What AI-native coders will need to learn
I increasingly think that people learning programming will need to learn more system-level thinking. They won’t need to know how to define a database, or the different kinds of indexes we might use, but they will need to know that databases exist, and that different types (relational vs. document) can affect performance and data integrity. They’ll need to know that programs can read from a variety of Internet APIs — and how to do so safely and securely. They’ll need to know how to provide an API for others to read from, and to consider the security implications of doing so. They’ll need to think about designing UIs using a combination of textual specifications, screenshots and sketches — followed by many iterations.
They’ll need to think about different document formats. About sending and receiving e-mail. About accessibility. About internationalization and localization. About what happens in the browser vs. on the server. About what languages we want to use, and why.
Most importantly, they’ll need to learn how to ensure that AI is writing solid, reliable code, both now and as it gets modified, extended, and debugged over time. This means teaching them, from the get-go, about automated testing, code coverage, mutation testing. Not to mention backups, frequent commits to Git, and extensive logs. And also security — making sure that any API, site, or app they create is as secure as possible from bad actors.
Compilers are deterministic, consistently turning the same source code into the same executable. Many programmers argue that AI is problematic because it’s fundamentally non-deterministic, and will produce different solutions each time it gets the same specification and instructions. I would counter that people, who currently write the majority of the world’s code, are also non-deterministic — and yet we’ve somehow managed to create incredible software over the years. But it’s true that we shouldn’t just trust AI to do the right thing all of the time.
I’m starting to put together a completely new “AI coding for non-programmers” course, which I’ll offer both on LernerPython.com and to companies around the world. (I’ll announce it to my Better Developers list when it’s ready.) I’m already playing with the ideas of what verbs and nouns an AI coder will need to know and understand in order to be effective. It won’t focus on Python, but rather on the problems that people and companies have, and how they can fix those problems using coding.
Every time programming has added a layer of abstraction, we’ve become able to solve larger and more complex problems, and more people have been able to join the fold of programmers. I believe that AI coding will do both — but it will radically change what coders need to learn, and how we teach them. I’m excited to take on this challenge, and look forward to discussing it with others in the industry.
The post Agentic coding means we’ll need some new abstractions appeared first on LernerPython.
November 01, 2026 03:20 PM UTC
Pandas multi-index: Working with 3D data using `.loc` and `.xs`
My students used to ask if Python Pandas supports 3D data structures.
Answer: No. Series are 1D and data frames are 2D.
But… a multi-index effectively gives you more dimensions. You can then navigate the indexes with .loc and .xs.
The post Pandas multi-index: Working with 3D data using `.loc` and `.xs` appeared first on LernerPython.
November 01, 2026 07:00 AM UTC
The Python Coding Stack
Notes from the Near Future • The Permanently Curious Stack
Things are changing around us. Quickly. Some fields are ahead of others, but all are moving in the same direction.
A year and a half ago, many programmers were intrigued by how AI could help them but most were confident they’d still be the ones writing most of the code.
Not any more.
In my work, AI tools now handle implementation better and faster than I could on my own. But I’m still in the driving seat.
I now spend most of my day interacting with AI agents. But I’m not lounging by the beach while my agents do stuff for me. I’m collaborating with my agents. Managing them. Guiding them. Bouncing ideas off them. Reviewing their work. Steering them.
It’s impossible to disentangle my contributions from my agents’ contributions when you see the output. It’s all intertwined. It’s a collaboration.
And since the AI agents are doing all the implementation, I can focus on the bigger picture, the bigger ideas, the creative aspects. I’m enjoying this process.
That’s why The Python Coding Stack today becomes:
Notes from the Near Future • The Permanently Curious Stack
I’ll still write about Python. That won’t change. The Python Coding Stack is now a section of Notes from the Near Future.
But I won’t write only about Python. That’s why this publication is changing, just like the world around it.
I’ll write about how I’m adapting to this new way of working. What I like about it. And what I don’t. What I’m experimenting with. What works and what doesn’t.
This applies to everyone, not just those interested in programming and Python.
You may also have noticed the Agents Unpacked section in recent months. The change in what I write about is not starting now. It started a few months ago as I found myself spending more and more time with agents rather than with Python (directly). This section is where I’ll focus on how AI agents work and what they are, since we all need to learn how these tools work. And I’m learning in public in this section. I’ll also write about my experiments and experiences using agents.
You’ll also see an Agent & Co. section in the menu. You won’t receive these posts in your feed by default, but you can turn them on if you wish! Twice a week, I’ll share a fun perspective about human-agent interactions. Think of it as a day in the life of Monty – that’s my agent’s name. But behind the light-hearted nature of these cartoons and comics, you’ll gain an appreciation of the realities of working with agents. There’s plenty to learn from these posts!
Here’s the first comic, published earlier today:
How about brain atrophy? Will I lose my sharpness by handing the coding over to agents? As you’ll see from my articles over the coming weeks, I don’t think that’s the case. Working with AI is not about being lazy but about focusing on other aspects of problem-solving.
But I don’t want to get rusty with coding, a skill I enjoy. That’s why I’m starting to learn Rust. So, there’s another new section here on Notes from the Near Future where I’ll be learning Rust in public. There’s nothing published in Getting Rusty yet, but expect the series to start before the end of this year.
By the way, you can customise which sections you receive. But I’d suggest exploring the new sections for a bit first, especially if you’re an AI-sceptic!
So here’s the new line-up for you on Notes from the Near Future • The Permanently Curious Stack:
I have some more ideas, too. But that’s enough change for one day.
This publication is three and a half years old. There are now over 9,000 subscribers, and that number is still growing daily. One constant in this publication has been that I’ve always published articles that I would want to read myself. That won’t change. In fact, that’s why this publication is broadening its focus.
Another constant throughout the years has been that I’ve always published the majority of my work for free, fully accessible to all. That won’t change, either. But I do publish content exclusively for premium subscribers, and some of my upcoming series will be available only for premium subscribers. It takes plenty of work to produce a publication such as this and keep it running for so long. The support from premium subscribers helps keep this publication thriving.
As always, feel free to reply to this post and any other post. Tell me what you’re working on, how your work is changing (or not), share your thoughts, views, anything, really.
See you in the next post or somewhere in the online world before then…
Stephen
November 01, 2026 12:33 AM UTC
October 31, 2026
The Python Coding Stack
Thoroughly Checked
Jaime Buelta
Software is a discovery process
The development of software is a relatively new discipline, and one that is constantly changing. The last couple of years have been an earthquake with the arrival of AI, but even before that, the field changed beyond recognition from one decade to the next. Still, there’s something that I think is part of its essence, and it hasn’t changed. It has been widely recognised for the last quarter of a century, since the Agile Manifesto. It is borderline impossible to know exactly what functionality a software project needs until it’s done. And... Read More
LernerPython blog, from Reuven Lerner
Pandas droplevel: Remove a level from a multi-index
To remove a level from a Python Pandas multi-index, use droplevel:
– “level” kwarg takes an int or string
– “axis” kwarg can be “index” or “columns” — or use 0 or 1, but I prefer the names
Returned data frame has the same number of rows, but index might have duplicates.
The post Pandas droplevel: Remove a level from a multi-index appeared first on LernerPython.
Seth Michael Larson
Extracting Billy Hatcher “Joycarry Game” ROMs with Python
Billy Hatcher and the Giant Egg contains a feature called “Joycarry Games” similar to Animal Crossing’s NES game “Advance Play” feature. I wanted to extract the ROMs for these mini-games just like I did for Animal Crossing. Doing so wasn’t as straightforward; the ROMs aren’t available directly in the disc filesystem like they are in Animal Crossing. To extract the ROMs I ported an existing Rust program to Python (“rewrite-it-in-Python”, anyone?) that receives and saves the ROMs from the game running in Dolphin using the GBA TCP and Joyboot protocols.
These games are simple, and I only really played one as a kid: Puyo Pop. The game is similar to “Dr. Robotnik’s Mean Bean Machine”, which was a favorite of mine. This was the only way I could take that game “on-the-go”, often downloading the game to my GBA before road trips to see my grandparents.
Joycarry Game menu in Billy Hatcher with “ChuChu Rocket! Challenge” selected
The Python program is a port of this MIT licensed Rust program by Icedude907 with added functionality to save the EWRAM data after the ROM has been transmitted to the program via GBA TCP. I’ve distributed this program via a GitHub Gist.
Using the program requires the Dolphin emulator and dumping the ROM of the Billy Hatcher GameCube disc you intend to download Joyboot ROMs from. In the case of Billy Hatcher you also need to have unlocked the five different eggs hidden in levels. The fastest way to get around this is to download a 100% save file for your game’s region and place the file into Dolphin’s save file folder.
To extract the ROMs, launch Dolphin and set the controller in port 4 to be “GBA (TCP)”; Billy Hatcher in particular only works if the GC-to-GBA link cable is plugged into port 4. Start Dolphin playing Billy Hatcher, navigate to the world map, and then select “Joycarry Game”. From here you can select each game to be downloaded to our “GBA”, and the program should display information about receiving the ROM data.
Language setting and Joycarry ROMs
Something I did not know was that two of the five Joycarry ROMs, “ChuChu Rocket! Challenge” and “Puyo Pop”, have translations for both English and Japanese. Which Joyboot ROM translation is sent to you depends on the game region and which language is selected in the menu.
“ChuChu Rocket! Challenge”
“Puyo Pop”
The NTSC region (GEZE8P) of the game only supports English (no language selector in options) and only has English Joycarry ROMs. The NTSC-J region (GEGJ8P) supports Japanese and English, sending the corresponding Joycarry ROM depending on which language is selected. The PAL region (GEZP8P) supports English, French, German, Spanish, Italian, and ... Japanese! I checked each language, and the English Joycarry ROM is sent for all languages except Japanese.
Here are the SHA256 checksums of each ROM by game title and language:
| ROM Title | Language | SHA256 |
|---|---|---|
CHU2 AGB |
EN | 131258b587b4724ea06a5a0fbdce4d6ec05c8e63ef6b10a6000dfa8efd57c435 |
CHU2 AGB |
JP | 5adc33400eead9ce3d327377b7ce150a48e632abc2494370acb0b6ed61c1337a |
NIGHTS |
EN | 944fadb8fac3abf8c7db38f837677be3d3a664c56e6c8eb58e9e1949a10ac5f9 |
BILLYHATCHER |
EN | 128afd1c40a65831bd013c2c91abdadd816155df2b1a5456a7af6d260d48108e |
BILLYHATCHER |
EN | 2af4d14151981c2341c193cd2cc3d38e10dee1336ebedcd264f8e8bcb5e1f87e |
MINNADE PUYO |
EN | e769bd190bee6735a97cd239f587e3921108073a6f20ab20b8d62ba9c447cc12 |
MINNADE PUYO |
JP | 521f6a2a0876f2685205c0cfbfde934c14b8b3a6b5c173f4aa9fdfe93aed80a5 |
Happy Halloween! 🎃👻
Thanks for reading ♥ I would love to hear your thoughts! Contact me via Mastodon, Bluesky, or email. Browse the blog archive. Check out my blogroll.